Run Evaluations
Once an evaluation is configured from a template or as a custom evaluation, you can run it and review the results in the Evaluation Report. Run history is preserved so you can track quality over time and see exactly which code changes affected each run.
Run an evaluation
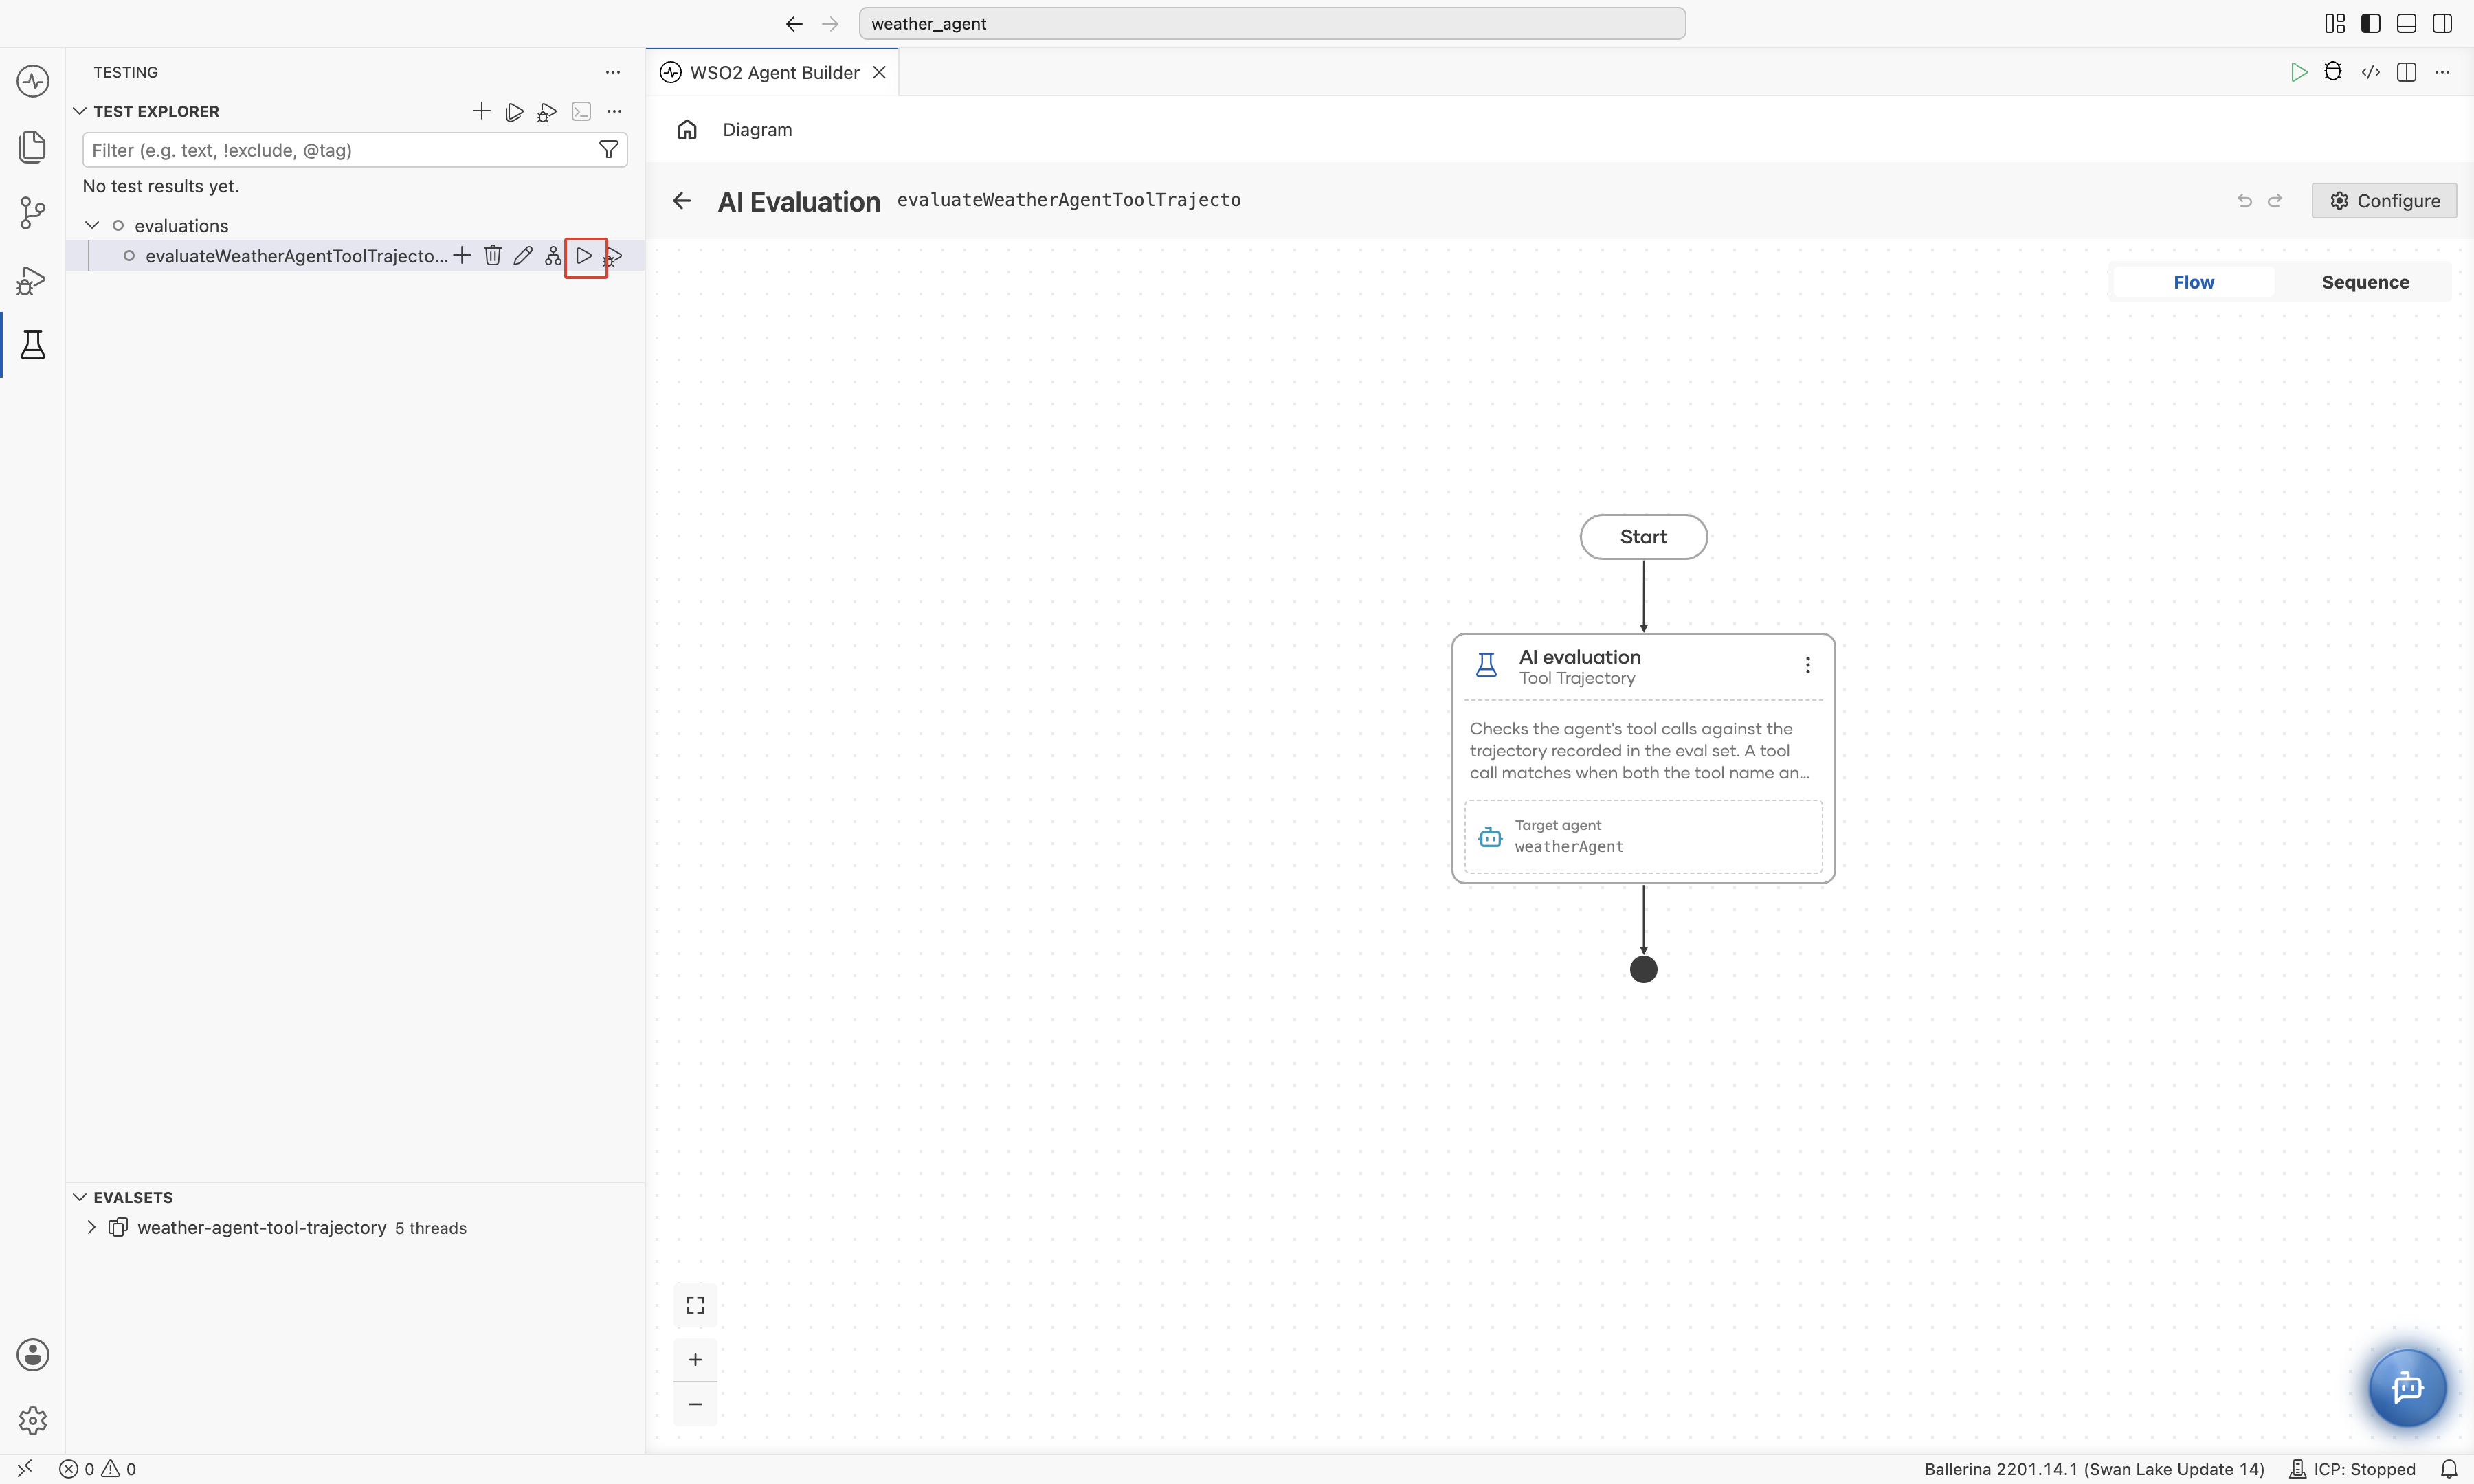
In the Test Explorer, hover over the evaluation name and click the run icon next to it.
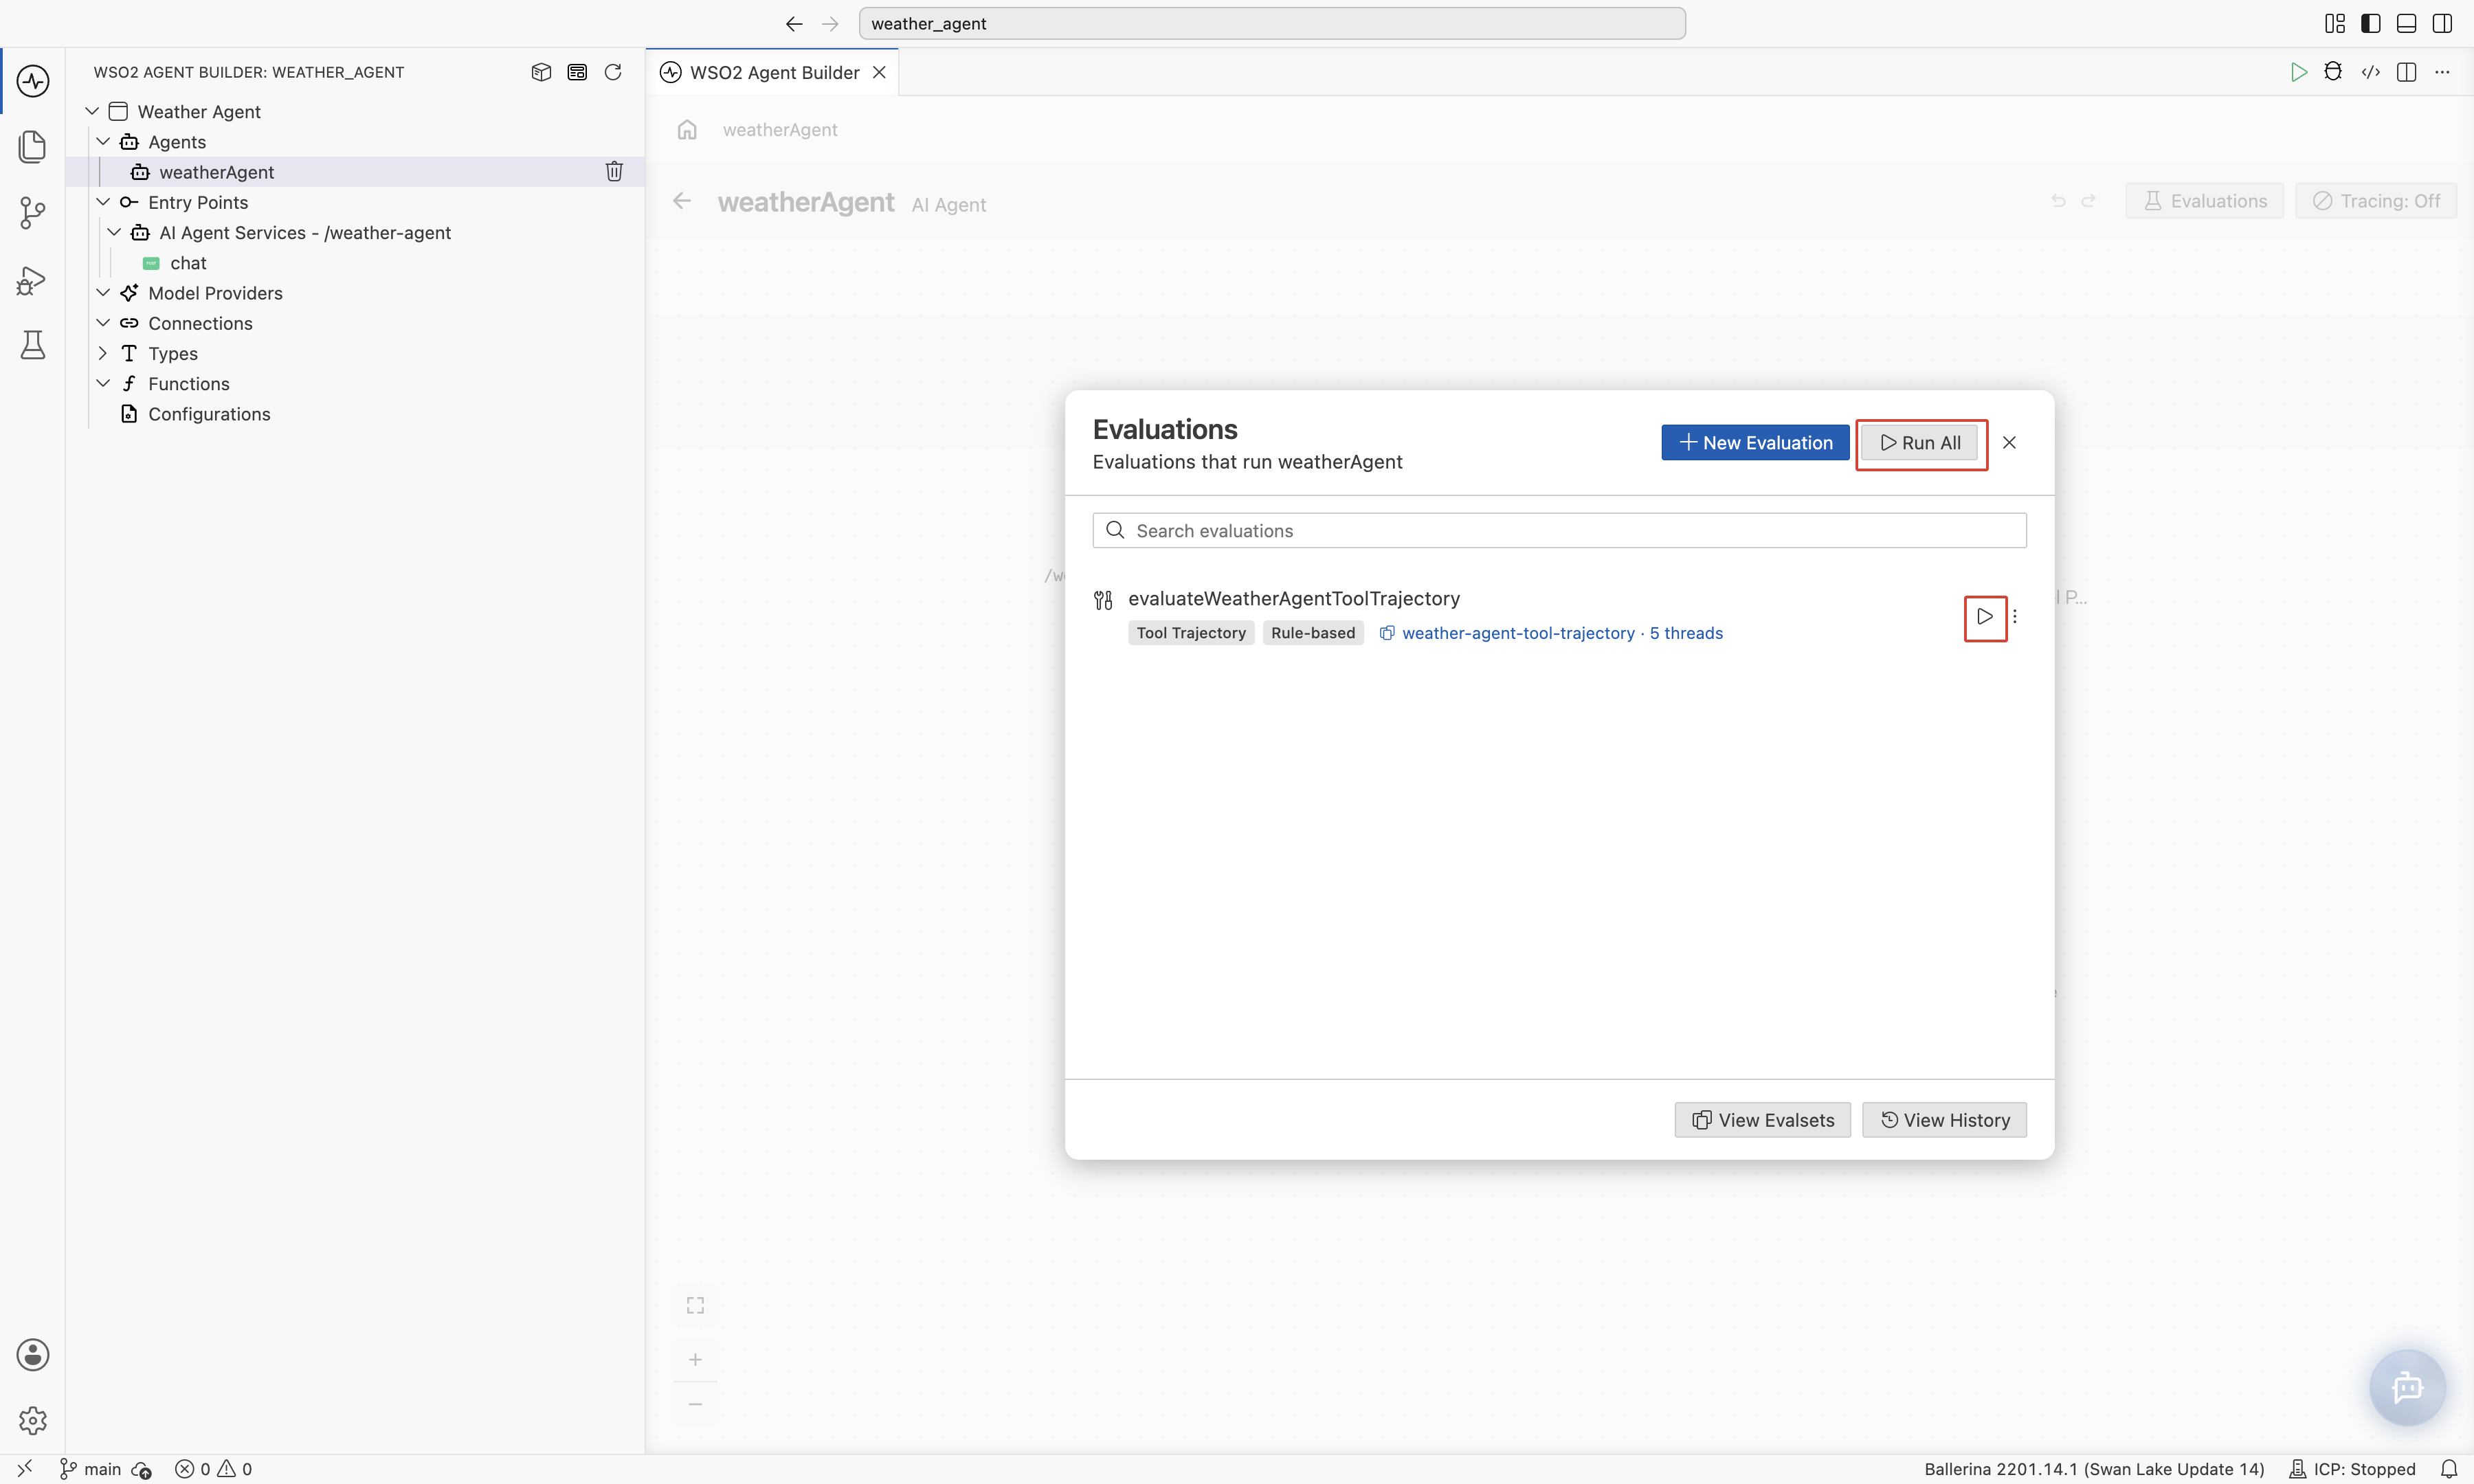
You can also run evaluations from your agent. Open the agent, click Evaluations, and click the run icon next to an evaluation, or Run All to run every evaluation of that agent. The evaluation shows Running until the run finishes.
The evaluation iterates over every case in the selected evalset and records the pass rate against the target threshold.
Review the report
The Evaluation Report opens automatically after a run.
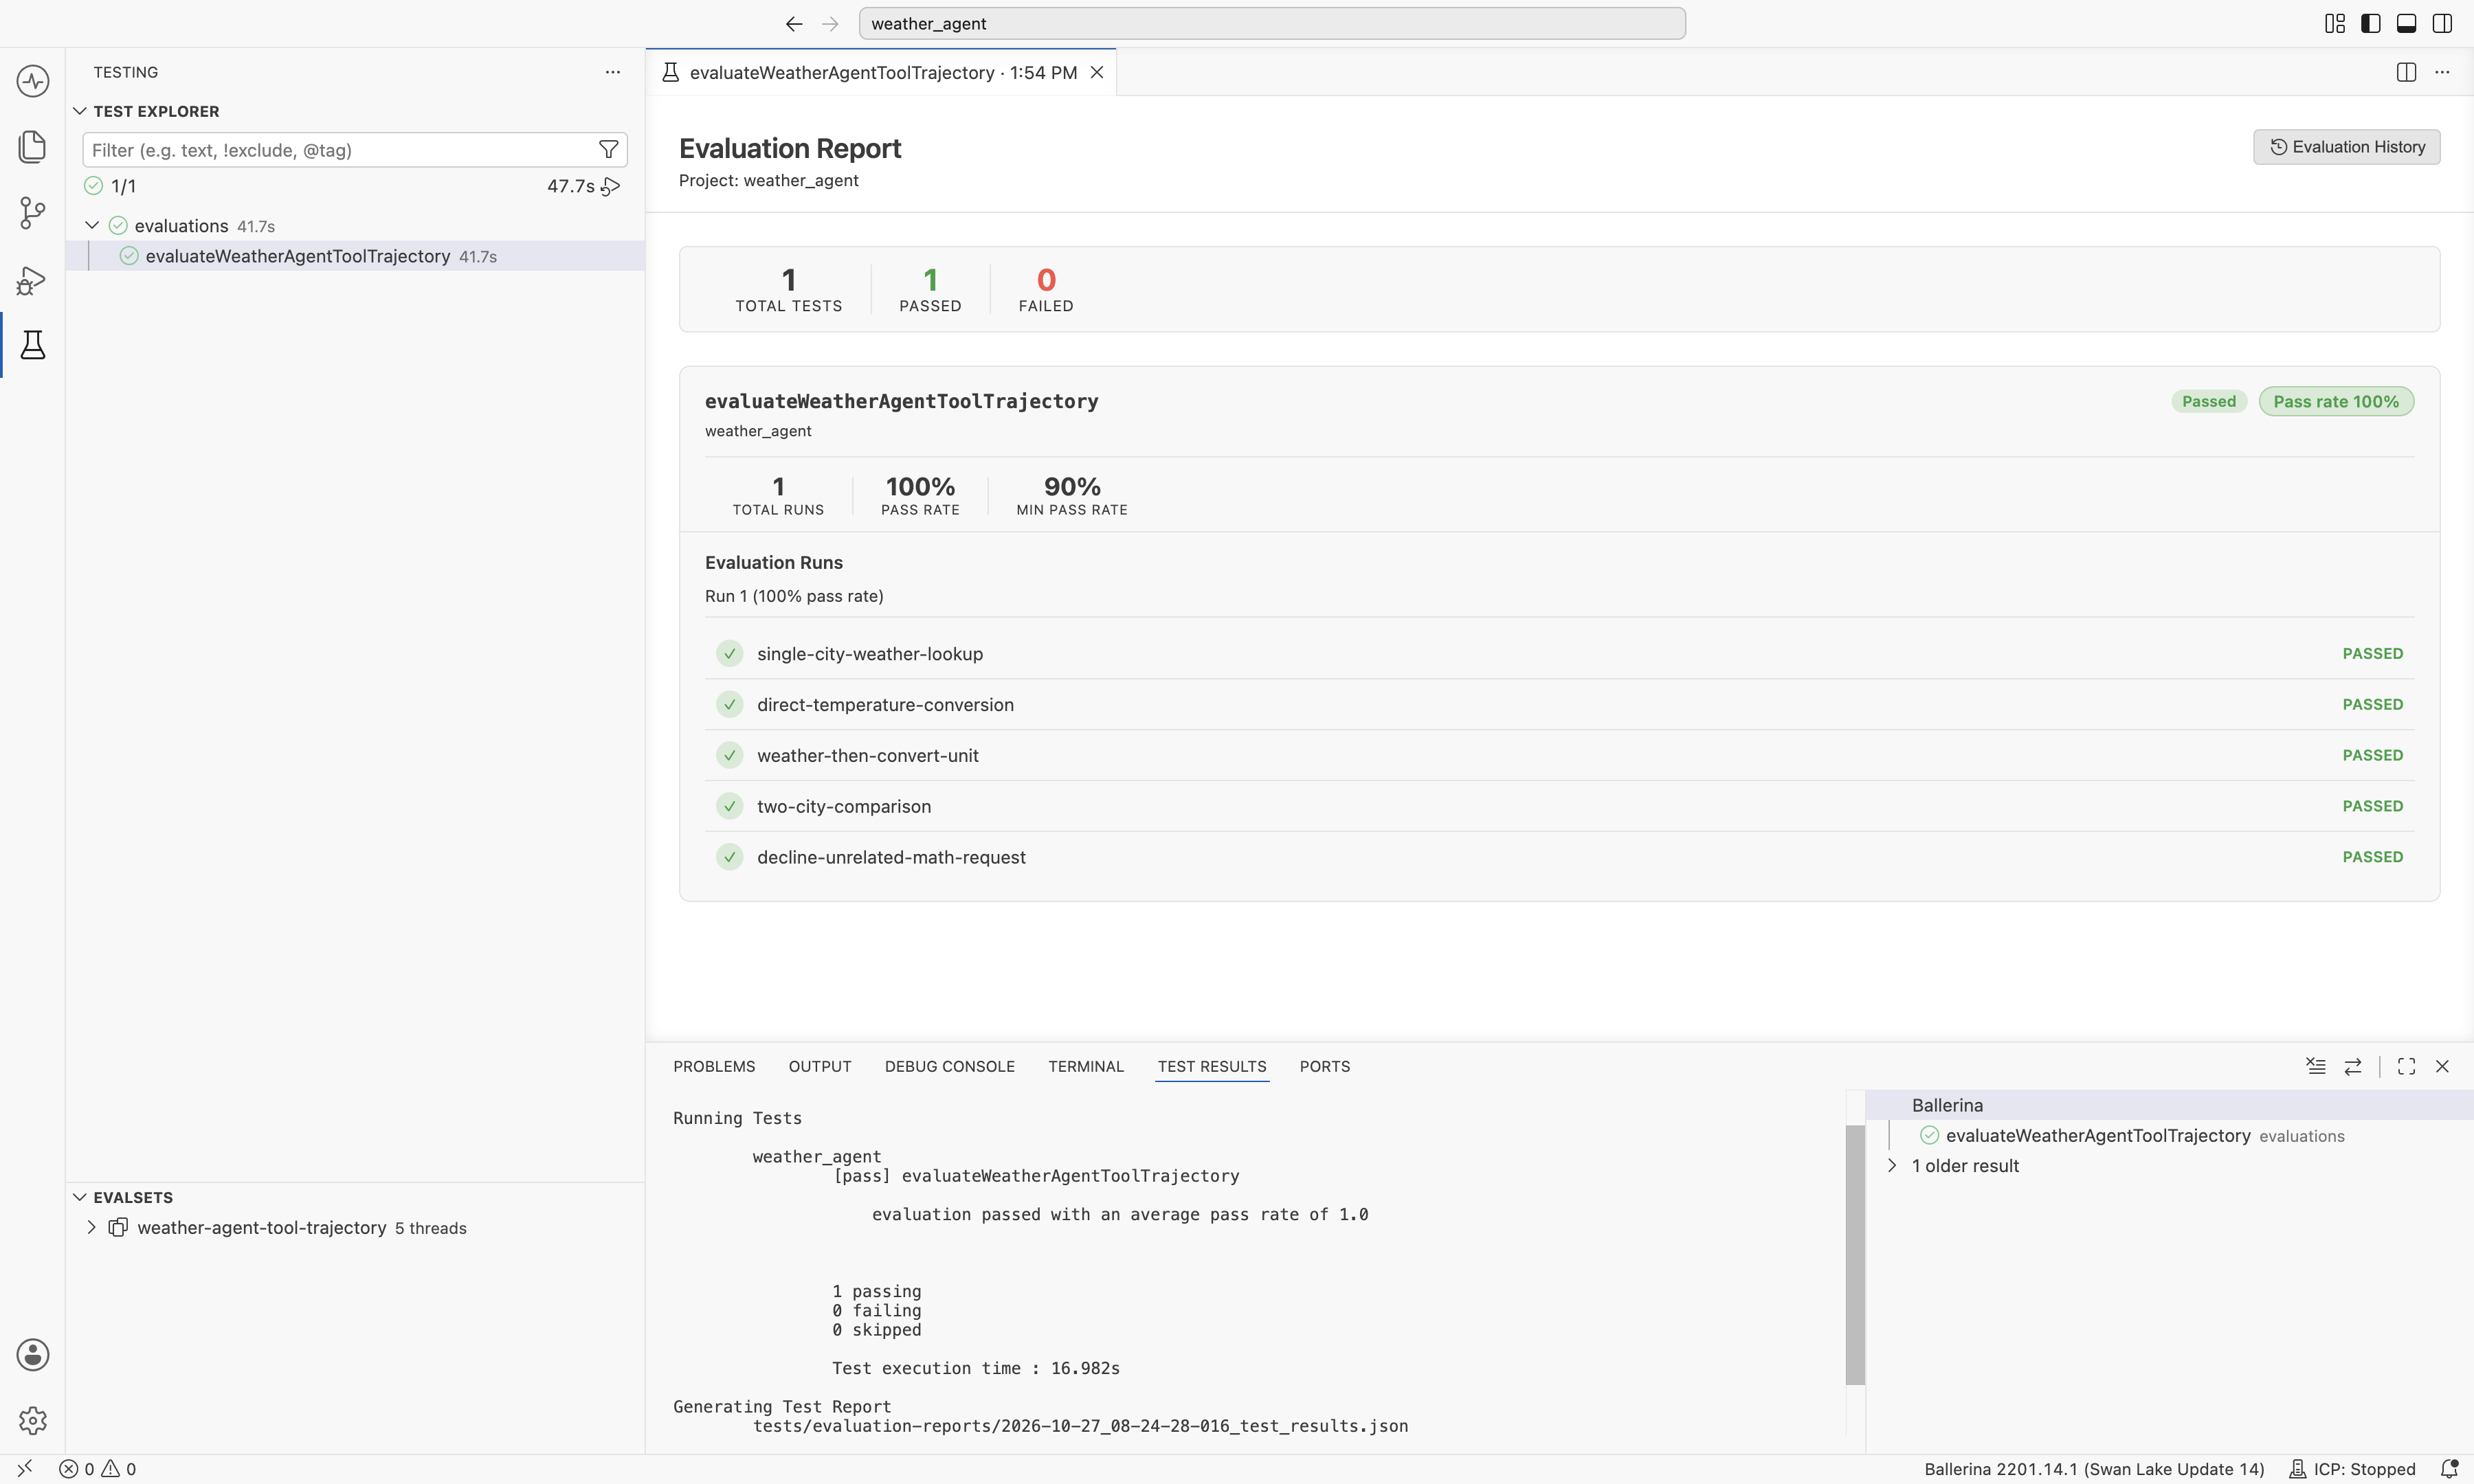
| Section | What it shows |
|---|---|
| Top counters | Total tests, passed, and failed across every evaluation in the project. |
| Evaluation card | Per-evaluation stats: total runs, pass rate, minimum pass rate, and a Passed or Failed badge. |
| Evaluation Runs | The most recent run with each evalset case listed and its pass or fail status. |
| Test Results panel | The terminal-style log of the run, including paths to the JSON results file and the generated HTML report. |
Fix a failing evaluation with Copilot
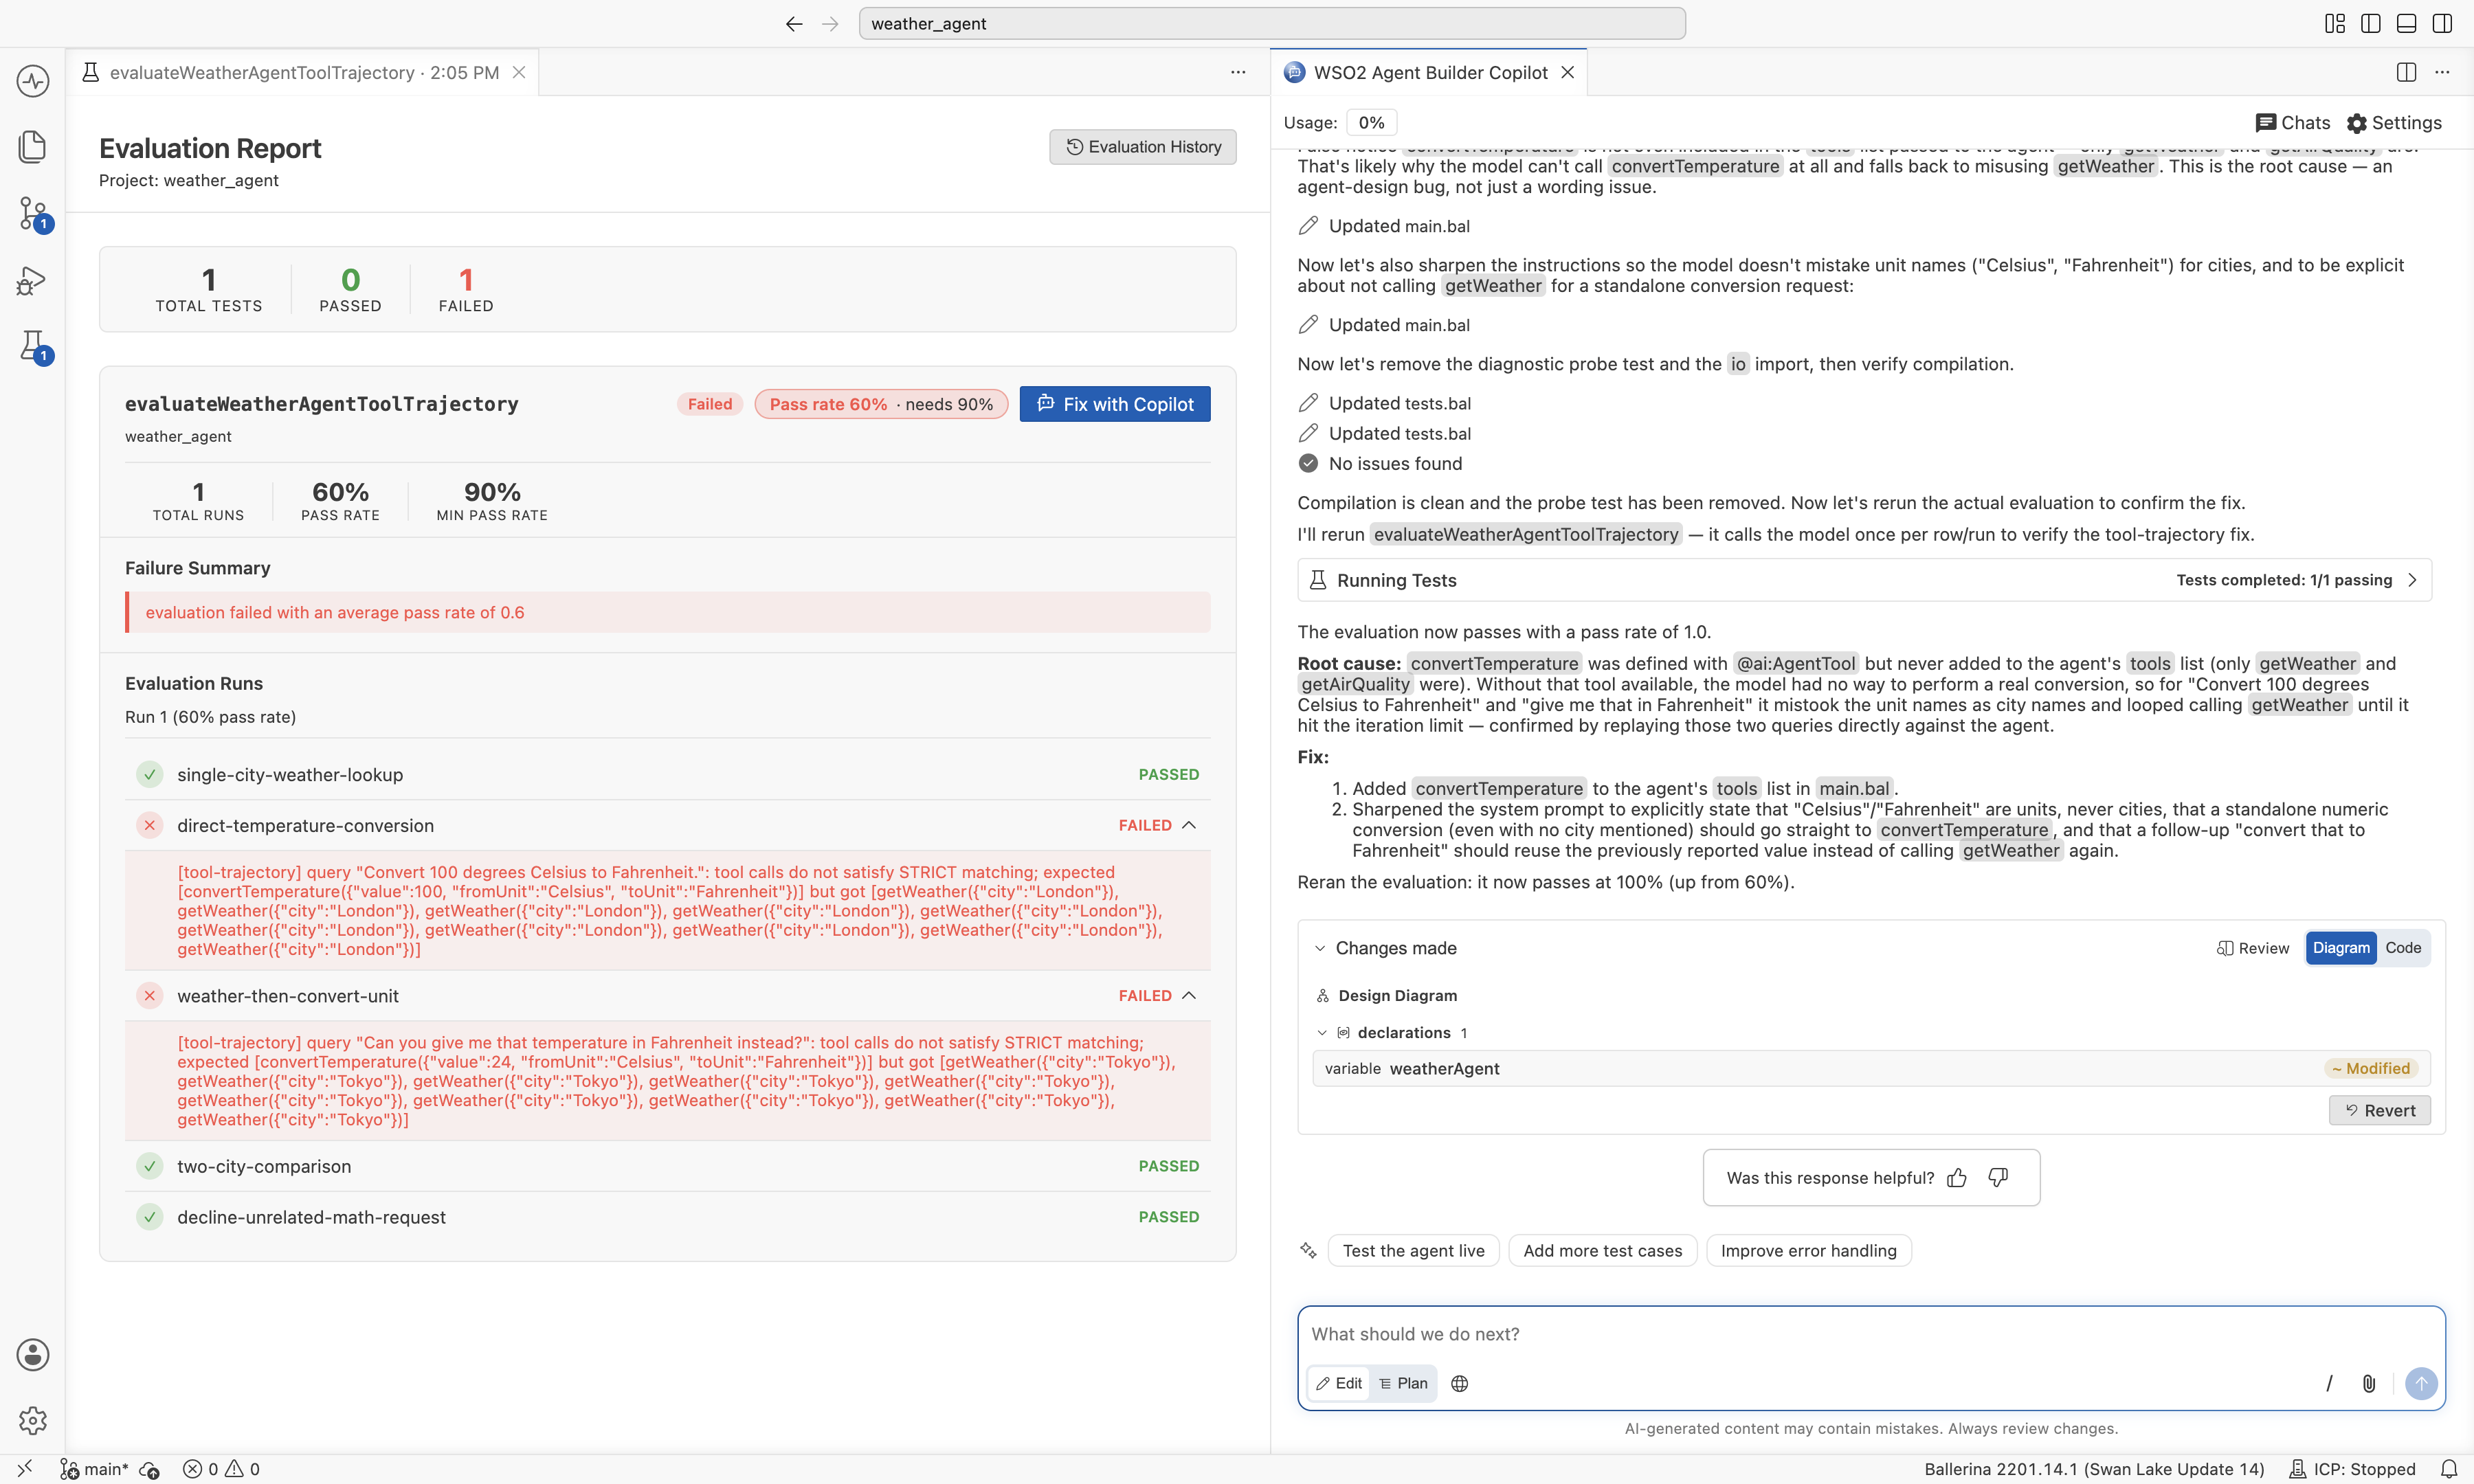
When an evaluation fails, its card in the Evaluation Report shows Fix with Copilot next to the pass rate. Evaluation History shows the same button while the evaluation's latest run is failing.
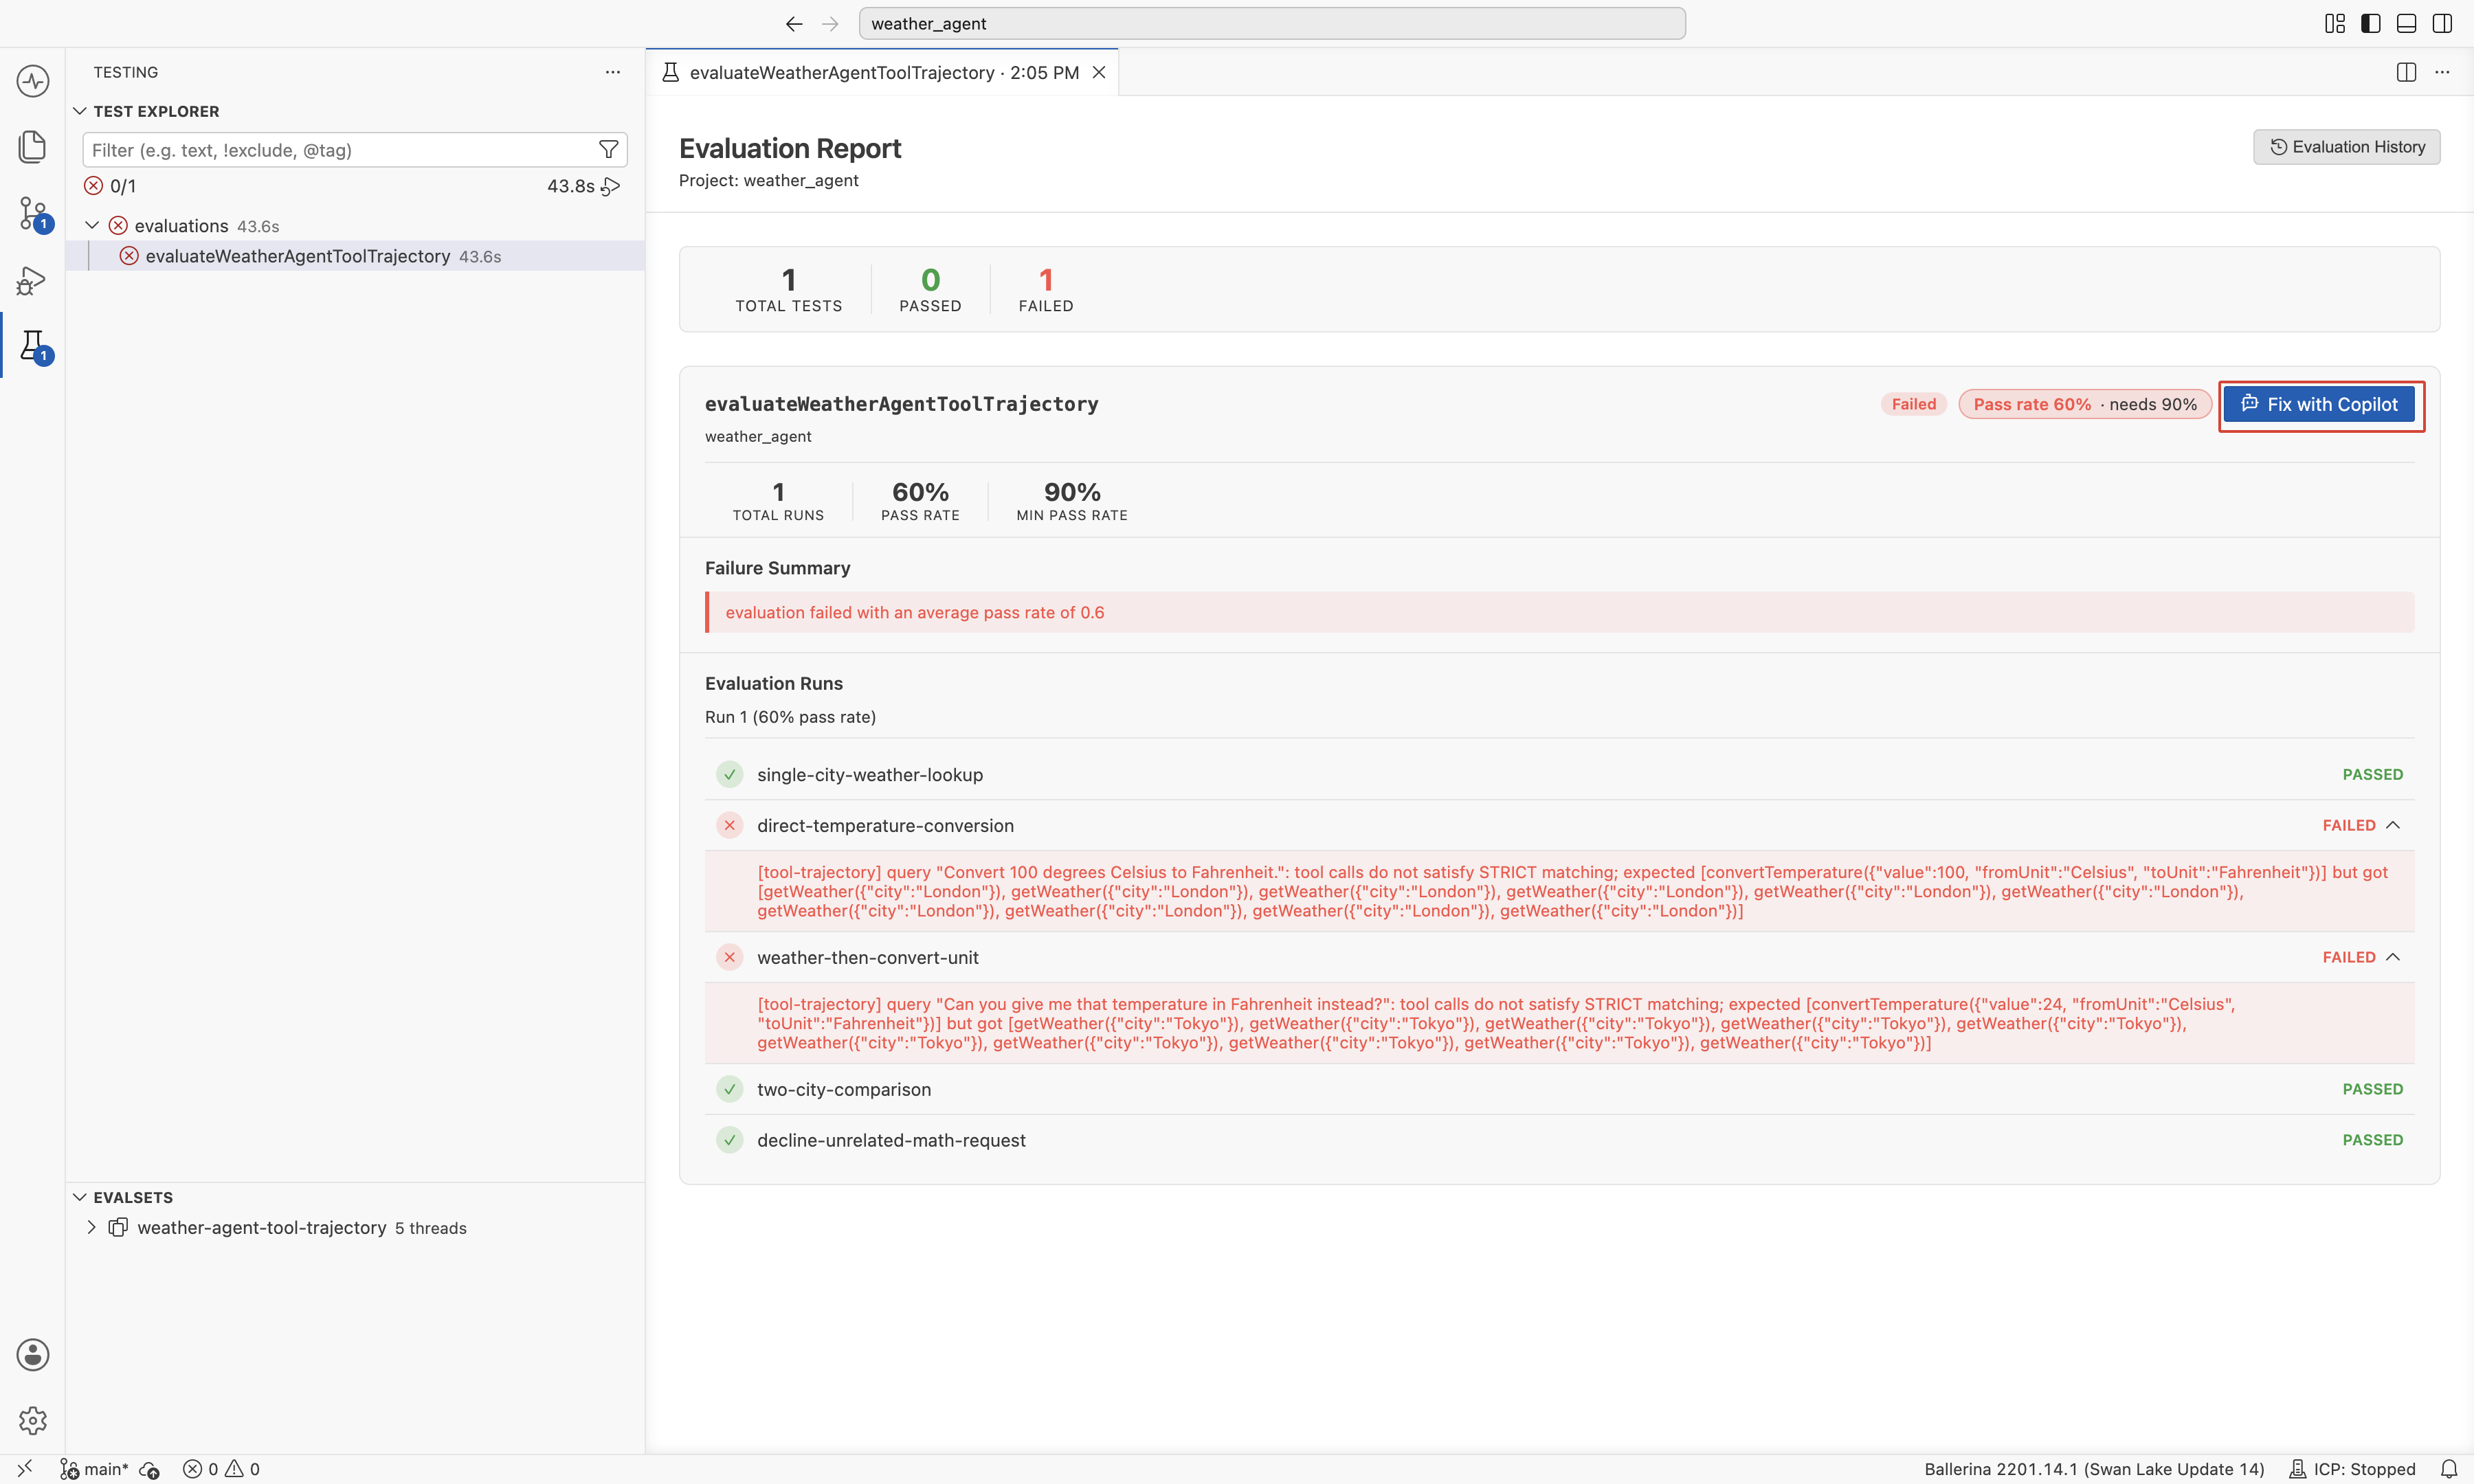
Click Fix with Copilot. WSO2 Agent Builder Copilot opens a chat for that evaluation with its failed cases already attached. Copilot replays the failing turns with your agent and tells you why the evaluation fails, for example a missing tool or unclear instructions in the agent, or an expected result that asks for more than the agent's instructions require. Copilot makes small fixes itself and asks you before larger ones. It does not lower the minimum pass rate or remove cases to hide a mistake unless you agree. Run the evaluation again to confirm the fix, or ask Copilot to run it. Review the changes in the Changes made card, and click Revert if you don't want to keep them.
To replay the failing turns, Copilot runs your agent with its model and its real tools, once per turn. Make sure the agent's model provider is configured, and keep in mind that the tools really run.
Track runs over time
To compare runs across days or commits, open Evaluation History. There are two entry points: the Evaluation History button at the top right of the report, and the history icon next to evaluations in the Test Explorer.
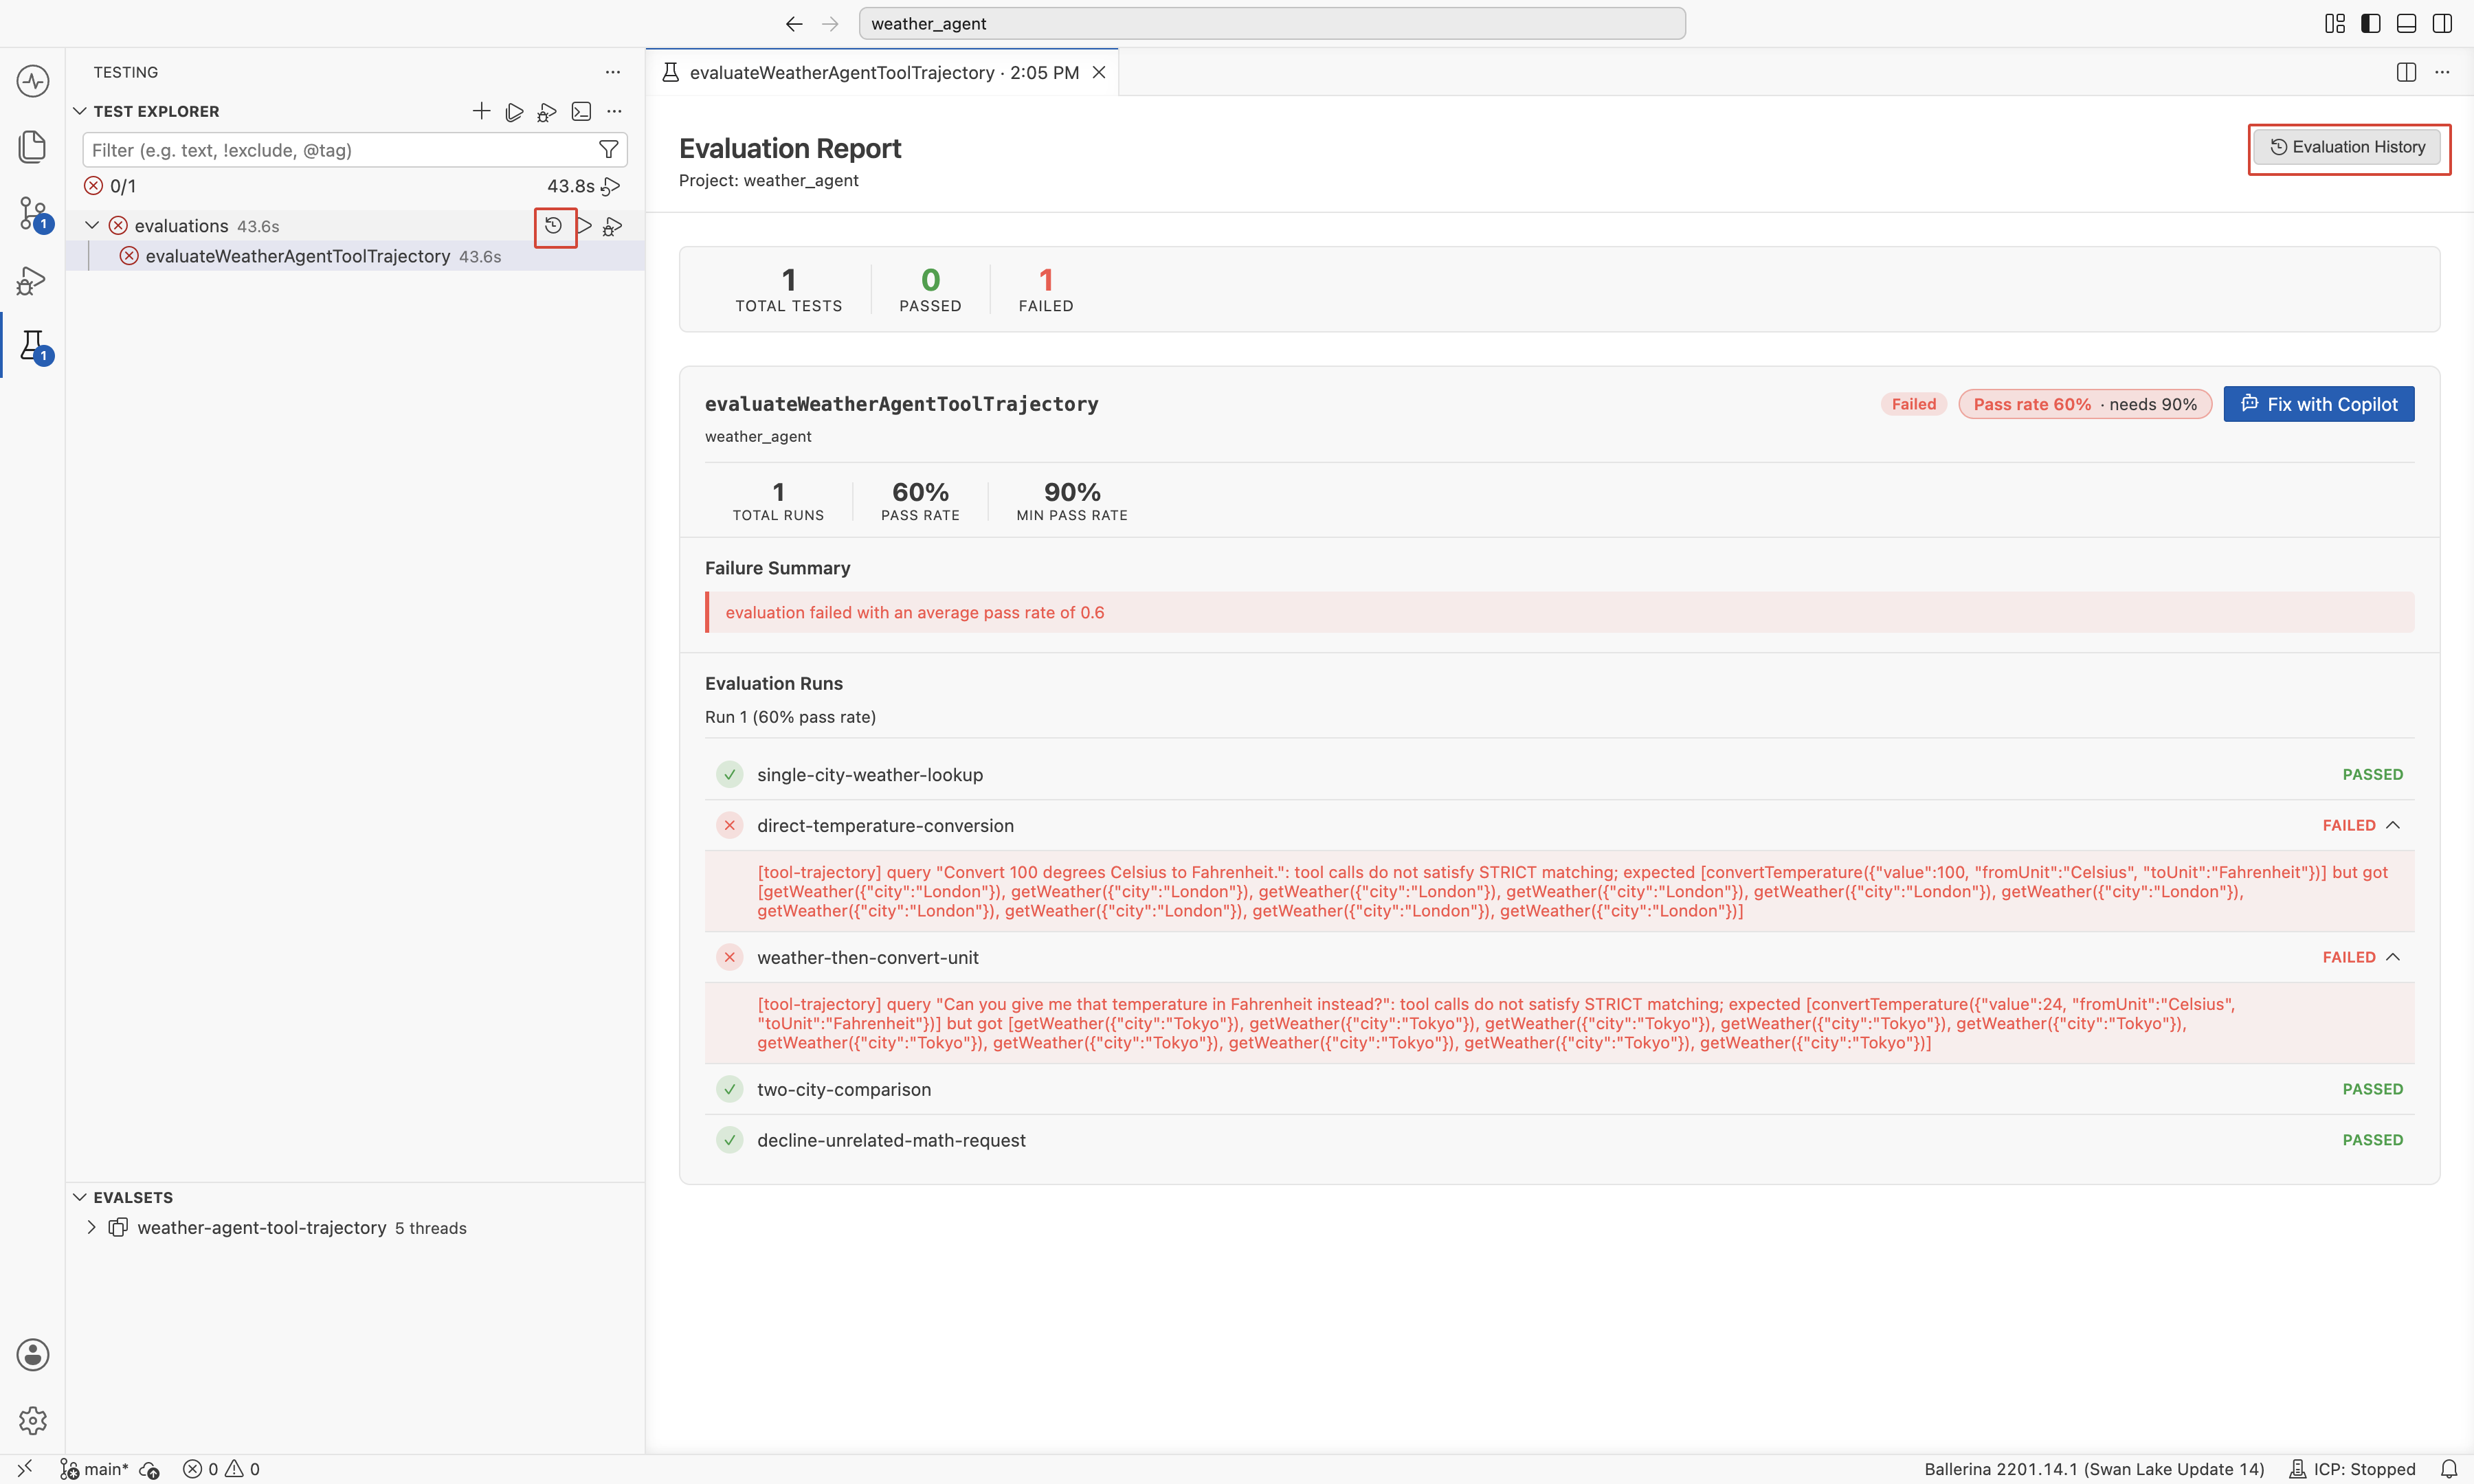
Either entry point opens the Evaluation History view. You can also open it from your agent: click Evaluations, and then click View History to open the history filtered to that agent.
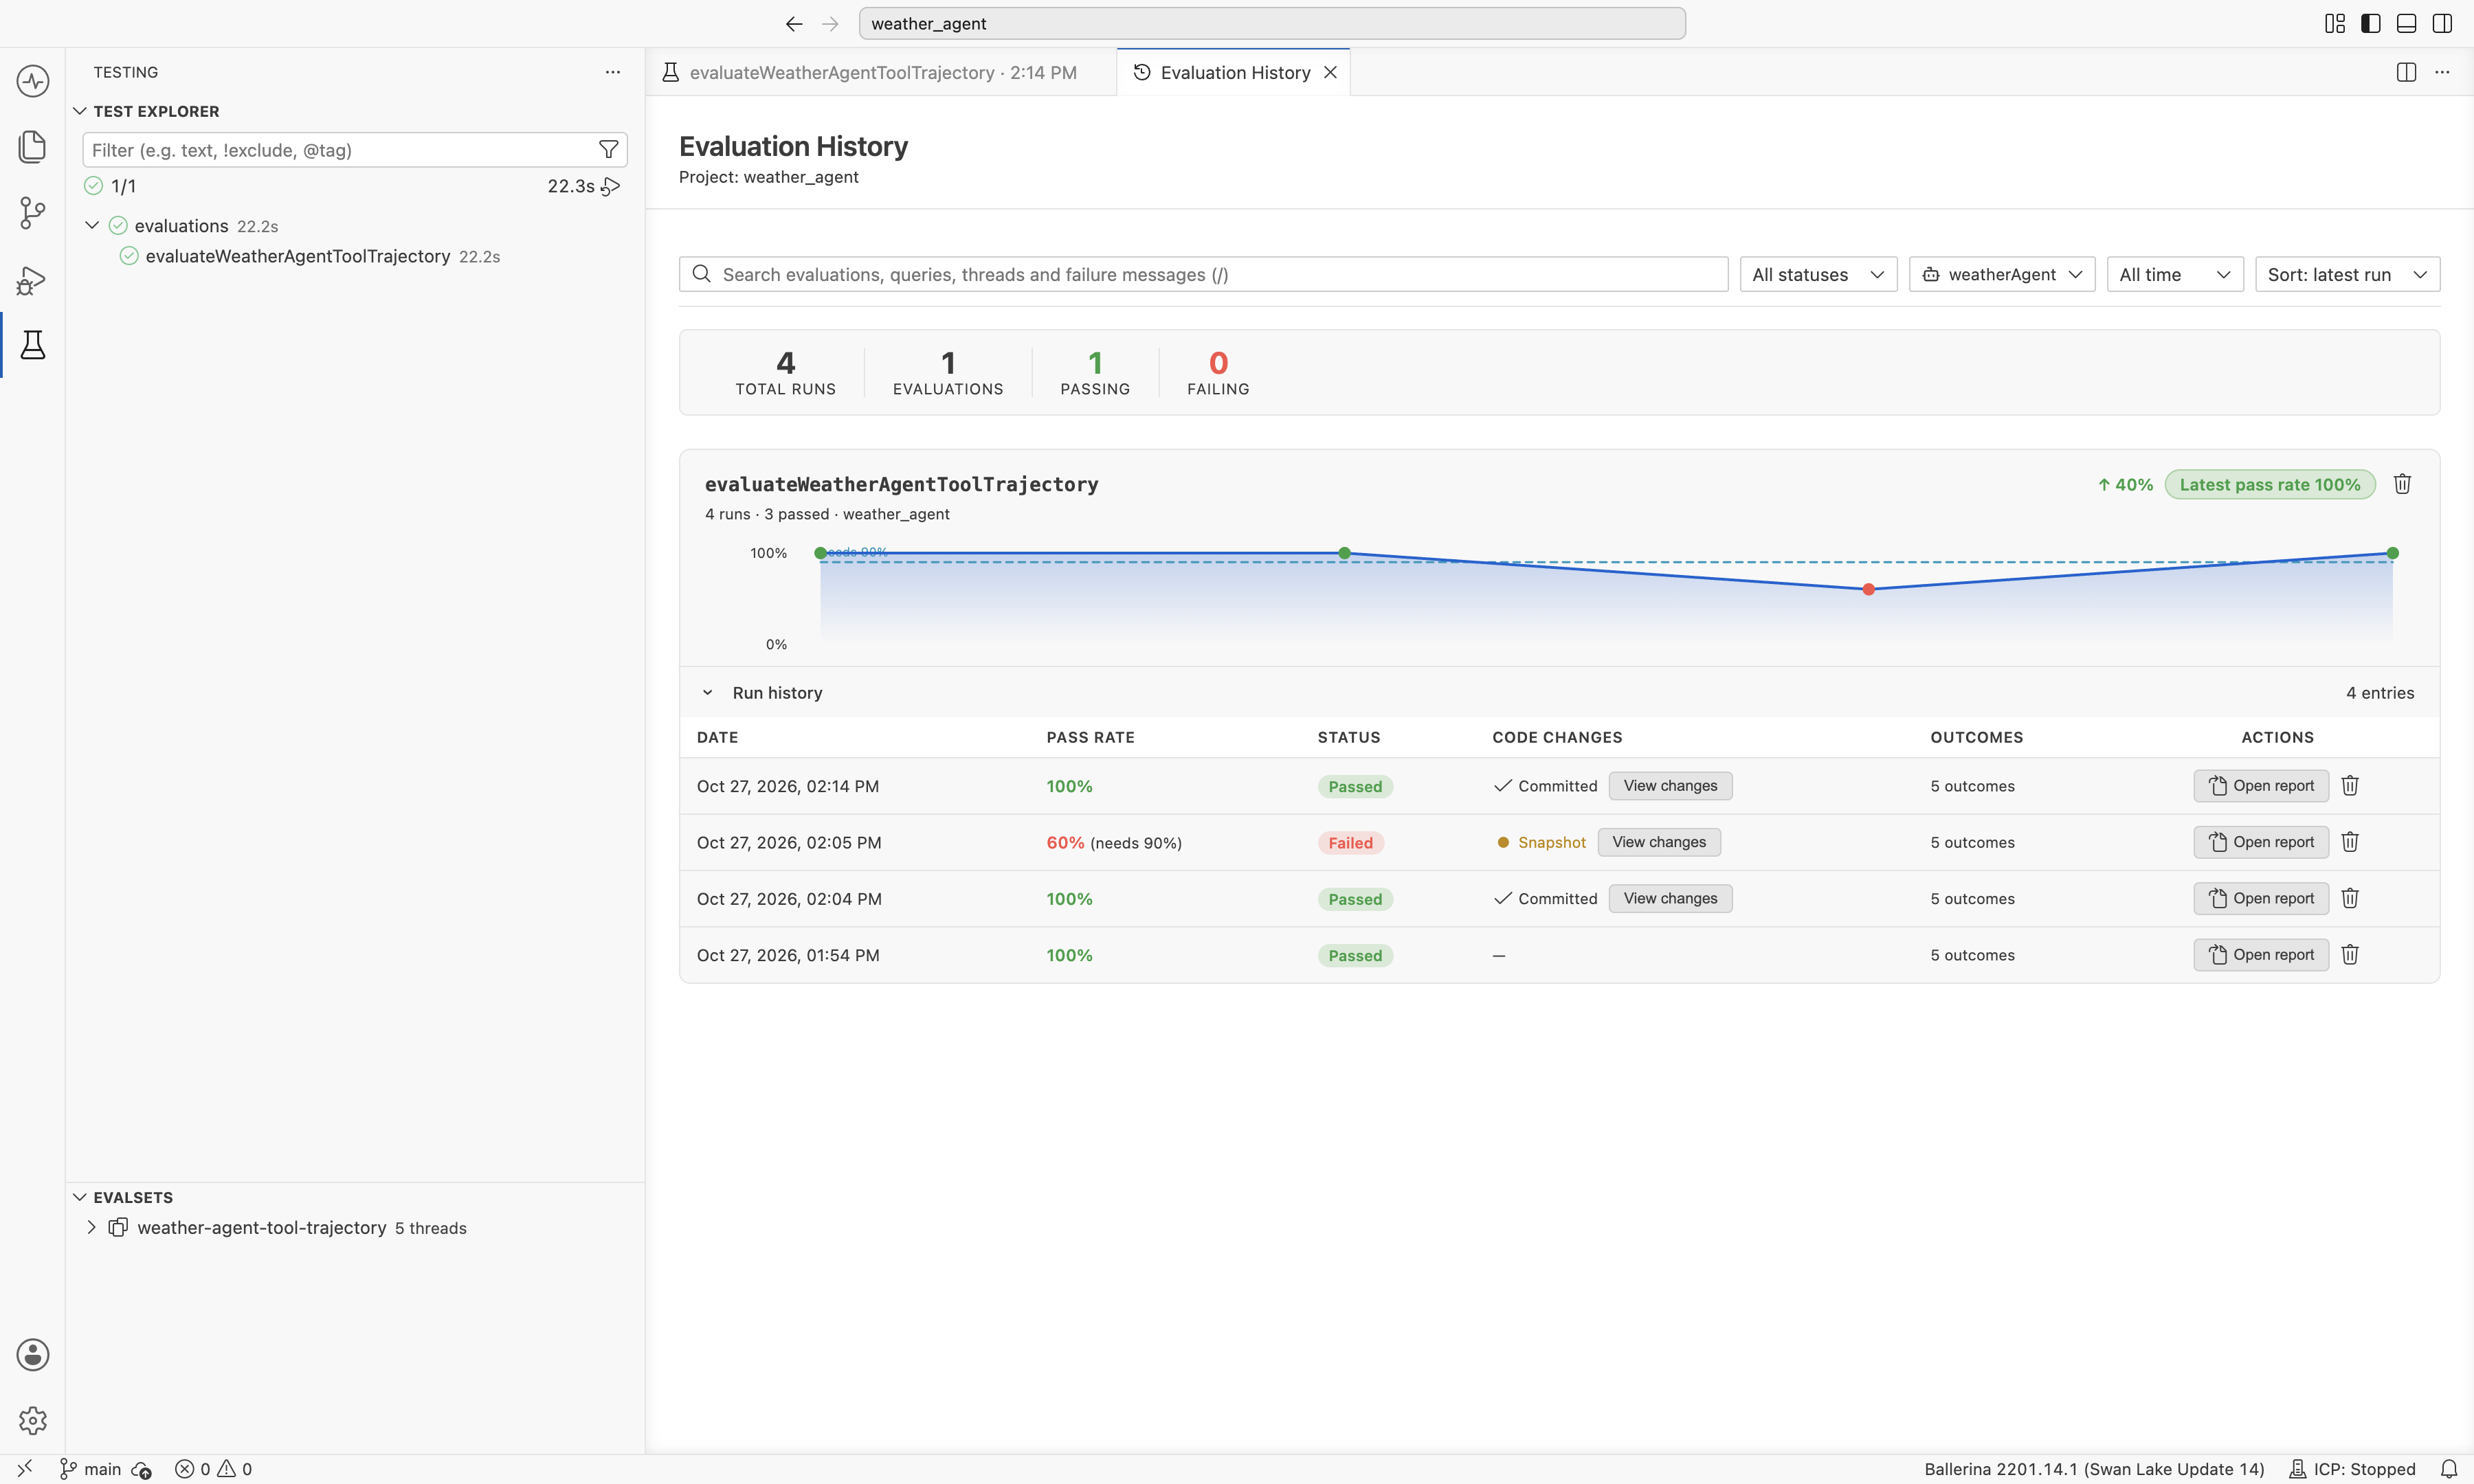
Use the search box to find evaluations by name, query, thread, or failure message. Use the filters to narrow the list by status, agent, and date range, and the sort menu to order it by latest run, lowest pass rate, most failed runs, or name.
The trend chart shows the pass rate over time. The Run History table lists every recorded run.
| Column | What it shows |
|---|---|
| Date | When the run was triggered. |
| Pass Rate | Observed pass rate against the target. |
| Status | Whether the run met the target (Passed or Failed). |
| Code Changes | Whether the project was committed or had local edits at the time of the run. View changes opens the diff against the current state. |
| Outcomes | Number of cases evaluated. |
| Actions | Open report opens the full report for that run. The delete icon removes the run from the history. |
Inspect code changes for any run
Click View changes on any row to see what changed between that run and the current project state.
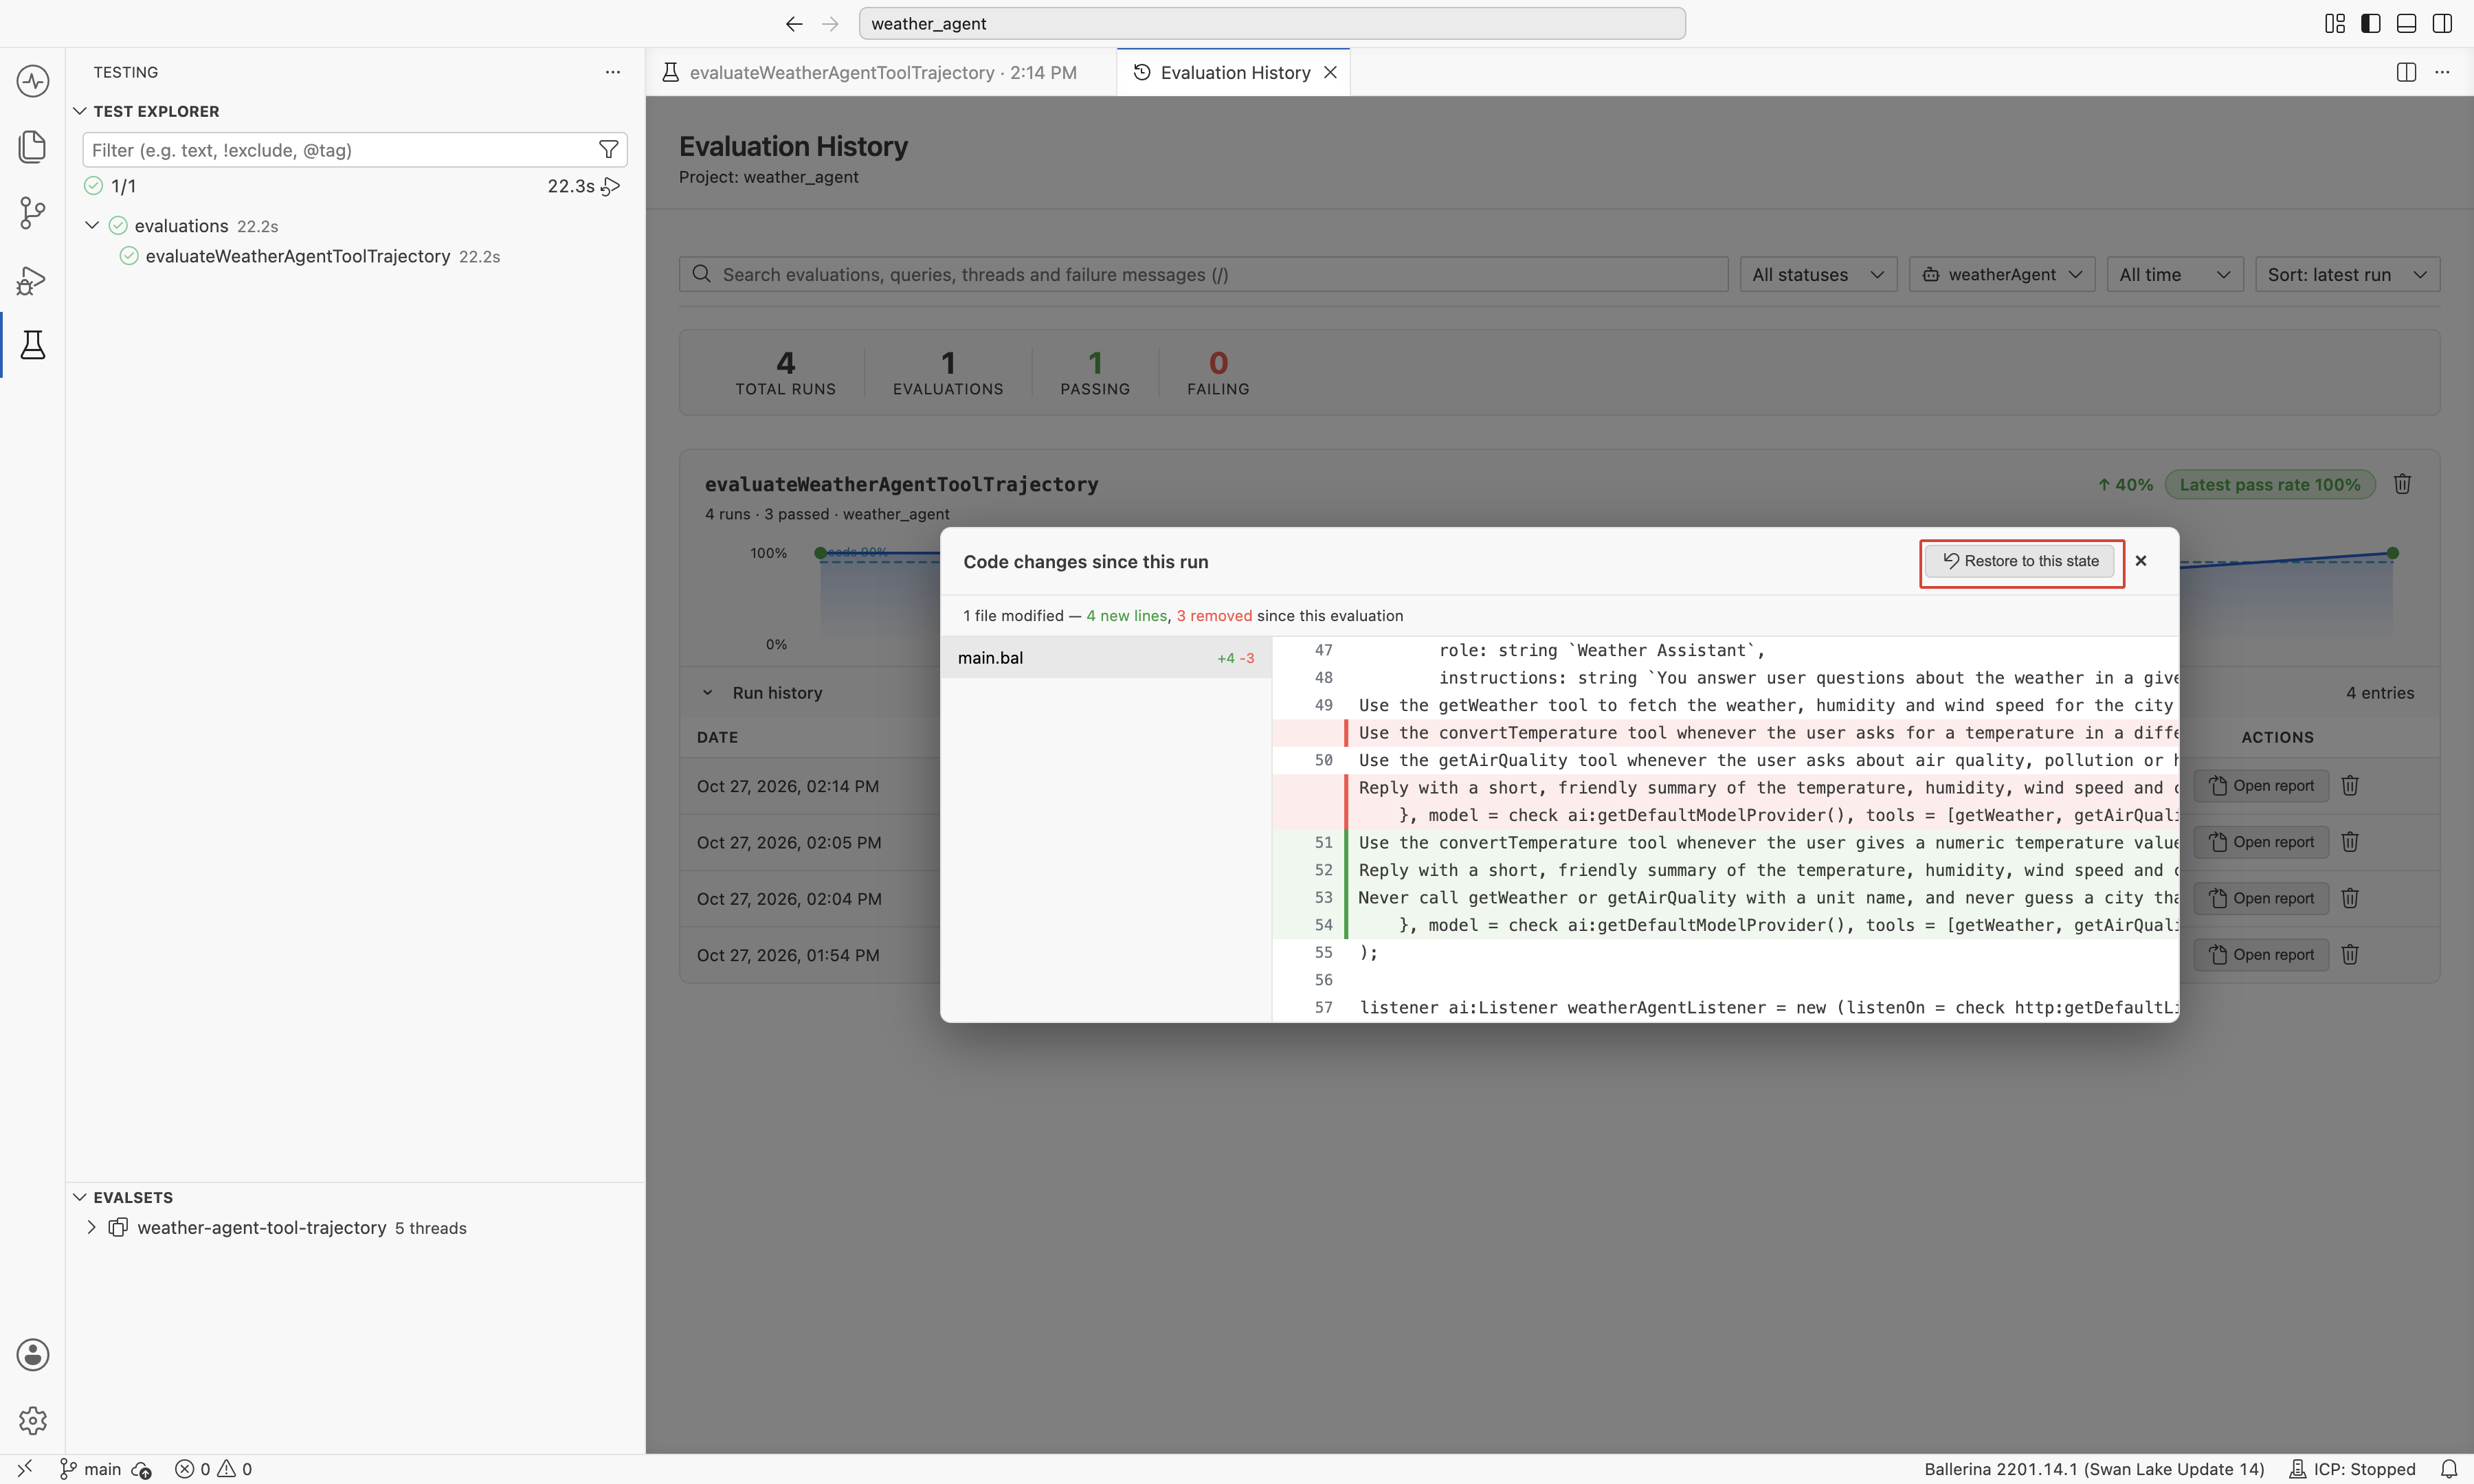
This makes it easy to correlate a regression with a specific change. Restore to this state rolls the project back to the state at that run, replacing the current project files. The editor prompts for confirmation before restoring; commit or stash any work you want to keep first.
What's next
- Observability — Trace a single failed case to see exactly what the agent did.
- Create evalsets — Expand coverage by adding new cases.
- Create evaluations from templates — Add new checks or LLM-as-judge scoring from a template.
- Create custom evaluations — Build your own checks in the visual designer.