Streaming LLM Responses: Patterns and Pitfalls
You set "stream": true, watch tokens roll across your terminal, and ship the feature. Then someone tries it in staging. The answer arrives all at once after a long pause, and nothing in the logs explains why. The model streamed fine. Something between the model and the browser waited for the whole response before passing it on.
Streaming LLM responses is a one-line change in an SDK and a much larger change in the system around it. This guide covers transport mechanics, provider event formats, when not to stream, the common pitfalls, and how an AI gateway handles streamed traffic.
Why Stream at All: The UX Case in One Paragraph
The metric that matters is time to first token (TTFT), the gap between sending a prompt and seeing the first piece of output. Streaming does not shorten total generation time. It lets the user start reading while the model is still writing. In Jakob Nielsen's widely cited limits, about 0.1 seconds feels instant and about 1 second keeps a user's flow of thought intact. Around 10 seconds is roughly the limit for holding attention on the task. Visible progress also changes how long people will wait. Nielsen Norman Group describes a University of Nebraska-Lincoln study on this. People shown a moving progress bar were willing to wait about three times longer than people shown nothing. A token stream is a progress indicator that also delivers the answer, which is why TTFT is the number to watch for interactive features.
How Streaming Works at the Transport Layer
LLMs generate text autoregressively. Each token depends on the ones before it, so output is produced in order, one piece at a time. A non-streaming API holds those pieces until generation finishes and returns a single JSON body. A streaming API writes each piece to the connection as soon as it exists.
The major hosted LLM APIs do this with Server-Sent Events (SSE). The response carries Content-Type: text/event-stream, and the body is a sequence of text blocks separated by blank lines. Each block holds field: value lines, most often a data: line with a JSON payload. SSE flows one way, which is all token delivery needs.
How those bytes are framed depends on the HTTP version of each connection. Under HTTP/1.1, a response of unknown length is usually sent with Transfer-Encoding: chunked. HTTP/2 disallows the Transfer-Encoding header and carries the body in its own frames instead. Transfer encoding is also hop-by-hop. Every intermediary decodes it and can re-frame, or hold, the body before sending it on.
So a stream is only as reliable as its path. A typical deployment has two separate HTTP exchanges. The inbound leg runs from your client to your service or gateway. The outbound leg runs from that service to the provider.
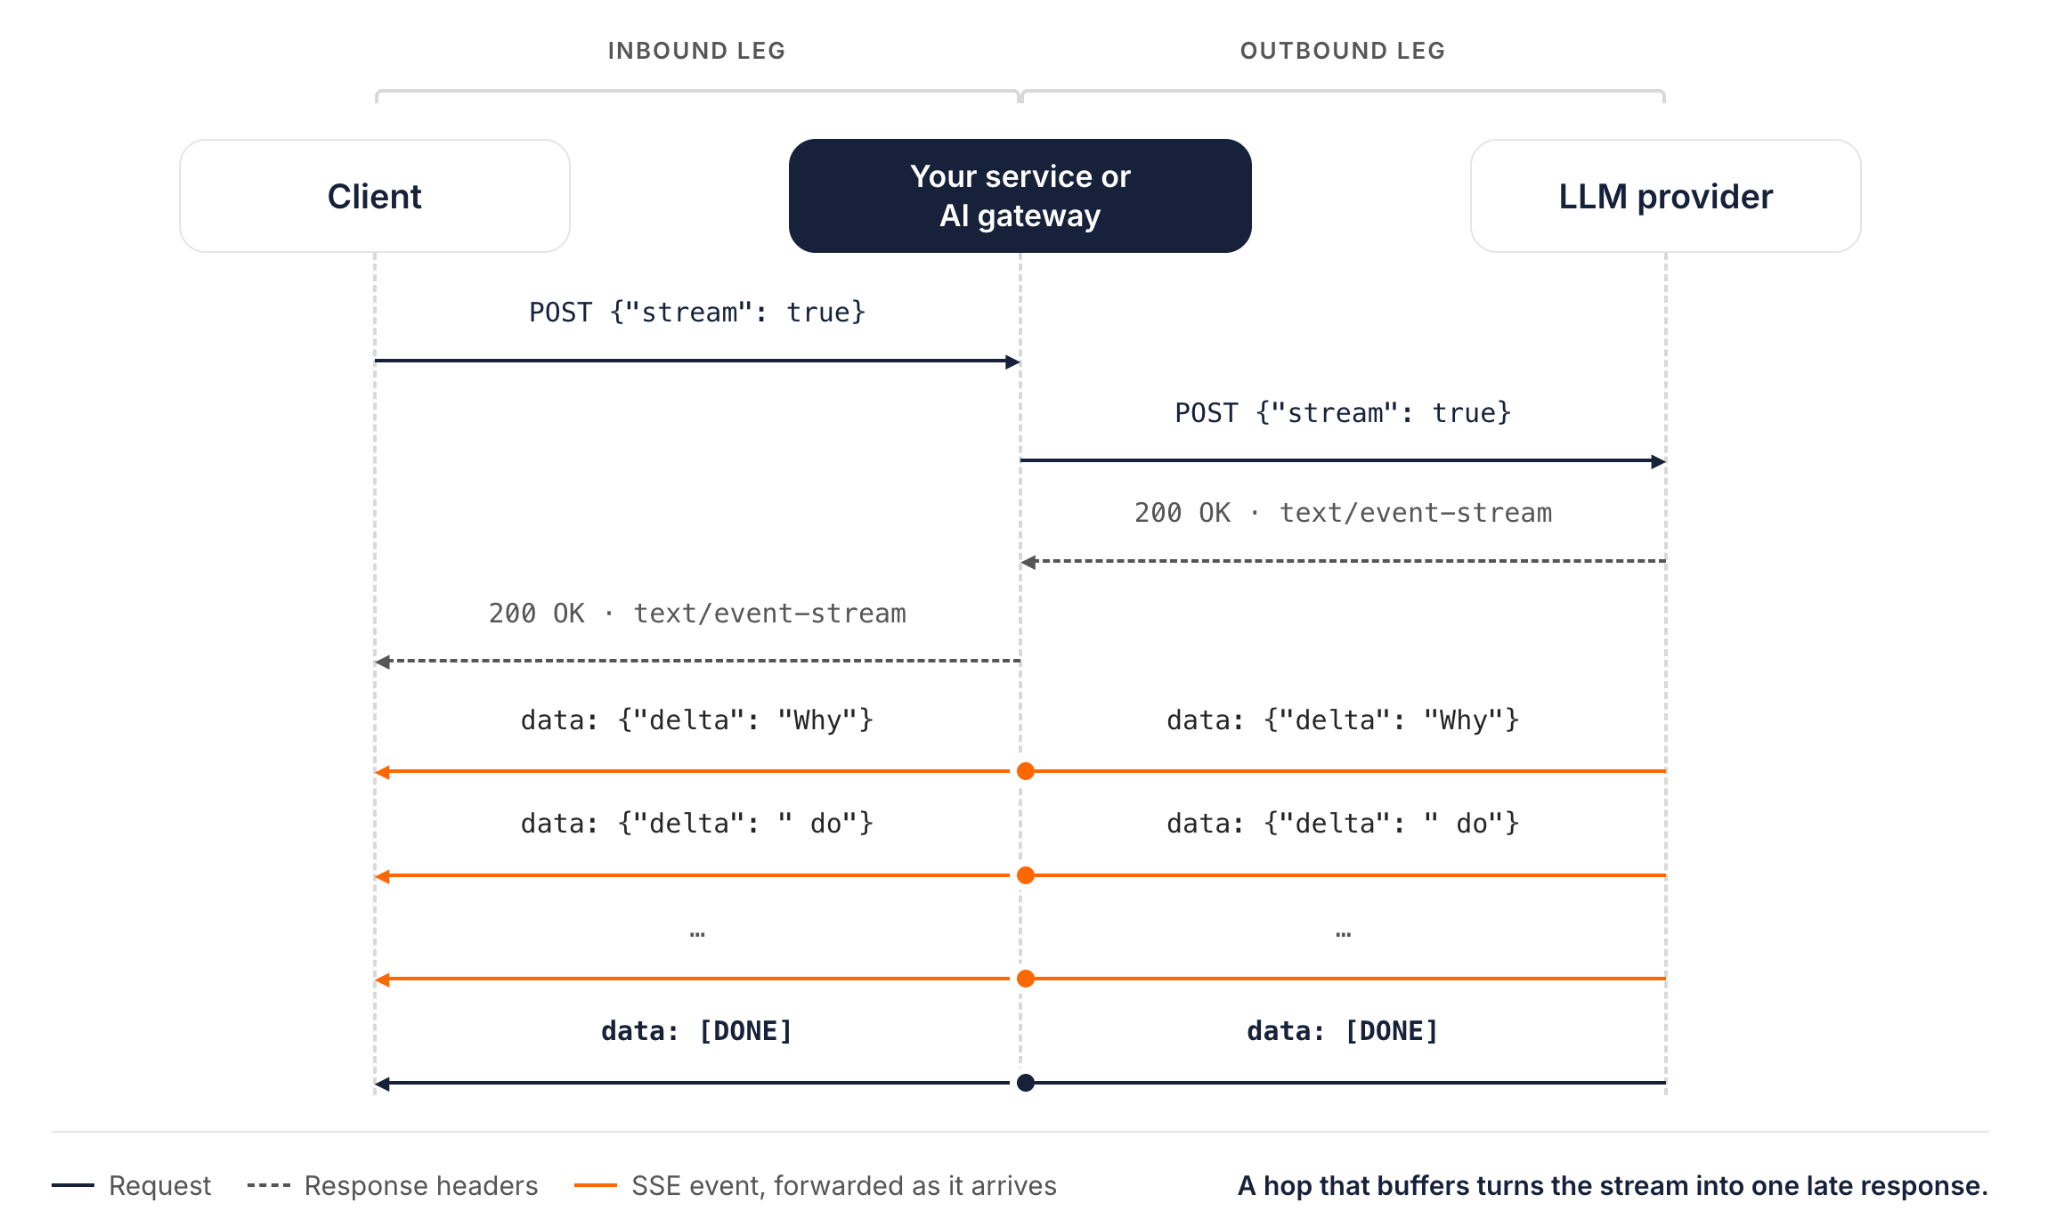
A load balancer, CDN, or ingress proxy may sit on either leg. None is required.
The diagram uses simplified, Chat Completions-style events. The data: [DONE] terminator and the delta payload are specific to that API. Other providers use different payloads and completion signals.
SSE in Practice: What Each Provider Actually Sends
OpenAI, Anthropic, and Google share the SSE envelope and differ in almost everything inside it. Simon Willison's walkthrough of streaming LLM APIs captured all three with curl. The table covers OpenAI Chat Completions, Anthropic Messages, and Gemini streamGenerateContent. The OpenAI Responses API uses a different set of typed events and is not covered here. The differences that matter most are how a stream ends and where token usage appears.
| OpenAI Chat Completions | Anthropic Messages | Google Gemini (streamGenerateContent) | |
|---|---|---|---|
| Event names | None. Every event is a bare data: line | Every event has an event: line naming its type | None. Every event is a bare data: line |
| Where text appears | choices[].delta.content | delta.text inside content_block_delta events | candidates[].content.parts[].text |
| End of stream | A literal data: [DONE] | A message_stop event | No sentinel in the captured stream. The connection closes after the last chunk |
| Token usage | Only when the request sets stream_options.include_usage. It arrives in one extra chunk with an empty choices array | Input tokens in message_start. Cumulative counts in message_delta | A usageMetadata object on each chunk, with counts that grow as output grows |
Here is an abbreviated OpenAI stream with usage enabled. The id, model, and created fields are trimmed for readability.
data: {"object":"chat.completion.chunk","choices":[{"index":0,"delta":{"content":"Why"},"finish_reason":null}],"usage":null}

data: {"object":"chat.completion.chunk","choices":[{"index":0,"delta":{},"finish_reason":"stop"}],"usage":null}

data: {"object":"chat.completion.chunk","choices":[],"usage":{"prompt_tokens":11,"completion_tokens":18,"total_tokens":29}}

data: [DONE]
All three APIs start a stream with a POST request. The browser's EventSource API only issues GET requests, so it cannot consume these endpoints directly. Browsers read them with fetch() and a stream reader, or through your own backend.
When to Stream and When Not To
Stream when a person is watching the output appear. Chat is the clearest case. Code generation is another, because developers read along and can cancel a run going the wrong way.
Streaming earns less, or costs more, in these situations:
- Batch and offline jobs: Evaluations and bulk classification have no reader waiting. Streaming adds parsing work and buys nothing.
- Output you must moderate before anyone sees it: OpenAI's cookbook notes that streaming makes completions harder to moderate, because partial completions are harder to evaluate. If policy says the full answer must be checked, the full answer has to exist first.
- Strict structured output: A JSON object is not valid until its closing brace arrives. Anthropic's docs describe streamed tool input as partial JSON strings that you accumulate and parse once the content block ends. If your code needs the parsed object, streaming only moves the parse to the end.
The Three Pitfalls: Reverse Proxies, Error Handling, and Reconnection
The reverse proxy problem
A reverse proxy that buffers responses collects the entire streamed body before forwarding it. The client still receives a correct answer with no error, but only after the last token. Nothing appears in the logs, which is why it is easy to miss.
NGINX is a common example. Its proxy_buffering directive is on by default. With buffering off, NGINX passes the response to the client as it is received. An upstream can also switch buffering off for one response by sending X-Accel-Buffering: no. Compression middleware, CDN settings, and ingress controllers can do the same.
To diagnose it, test each hop. curl -N turns off curl's own buffering, so you can see whether events arrive one by one.
# Outbound leg: call the provider directly
curl -N https://api.openai.com/v1/chat/completions \
  -H "Authorization: Bearer $OPENAI_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"gpt-4o-mini","stream":true,"messages":[{"role":"user","content":"Count to 30 slowly."}]}'

# Inbound leg: send the same body through your public endpoint
curl -N https://chat.example.com/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"model":"gpt-4o-mini","stream":true,"messages":[{"role":"user","content":"Count to 30 slowly."}]}'
The first hop where output stops arriving incrementally is the one to fix. Check timeouts too, since a long generation can outlast a default read timeout.
Error handling mid-stream
Once the server sends 200 OK and starts the body, the status code is committed. A later failure has to travel inside the stream. Anthropic documents this case directly. During periods of high load, a stream can carry an error event that would have been an HTTP 529 in a non-streaming call.
event: error
data: {"type": "error", "error": {"type": "overloaded_error", "message": "Overloaded"}}
The client has to tell three outcomes apart: a clean finish, an error reported inside the stream, and a connection that dropped without explanation. A clean transport finish still does not prove the answer is complete, so track three things separately. Transport completion means the endpoint's documented end-of-stream signal arrived. The provider termination reason says why generation stopped.
In Chat Completions, finish_reason can be "length" when the token limit cut the answer off, or "tool_calls" when the model needs a tool. Anthropic reports stop_reason, and Gemini reports a finishReason for each candidate. Application validation is your own check, such as parsing required JSON. OpenAI's API reference for stream_options also warns that an interrupted stream may never deliver the final usage chunk. Show partial output with an explicit incomplete status rather than presenting it as a finished answer.
In production, a provider SDK or a maintained SSE parser handles most of this. The Python example below shows the moving parts. It is scoped to text-only OpenAI Chat Completions streams with n=1, and tool calls are out of scope. It assembles complete SSE events before parsing JSON, forwards each delta as it arrives, records the finish reason, and keeps partial text when the transport fails:
import json
from collections.abc import Callable, Iterator
from dataclasses import dataclass

import httpx


class StreamError(Exception):
    """The provider reported an error inside the stream."""


class StreamInterrupted(Exception):
    """The stream failed or closed before [DONE]. Keeps any partial text."""

    def __init__(self, message: str, partial_text: str):
        super().__init__(message)
        self.partial_text = partial_text


@dataclass
class StreamResult:
    text: str
    finish_reason: str | None  # "stop", "length", "content_filter", ...
    usage: dict | None  # None means unknown usage, not zero usage


def sse_data(lines: Iterator[str]) -> Iterator[str]:
    """Assemble complete SSE events and yield each event's data field."""
    data_lines: list[str] = []
    for line in lines:
        if line == "":  # A blank line ends the event.
            if data_lines:
                yield "\n".join(data_lines)
                data_lines = []
            continue
        if line.startswith(":"):  # Comment or keep-alive.
            continue
        field, _, value = line.partition(":")
        if value.startswith(" "):  # The space after the colon is optional.
            value = value[1:]
        if field == "data":
            data_lines.append(value)


def stream_chat_completion(
    url: str, headers: dict, payload: dict, on_delta: Callable[[str], None]
) -> StreamResult:
    """Text-only OpenAI Chat Completions stream with n=1. Tool calls are not handled."""
    if payload.get("n", 1) != 1:
        raise ValueError("this example supports n=1 only")
    parts: list[str] = []
    finish_reason = None
    usage = None
    # The read timeout bounds each wait for the next chunk, not the whole stream.
    timeout = httpx.Timeout(10.0, read=120.0)
    try:
        with httpx.stream("POST", url, headers=headers, json=payload, timeout=timeout) as response:
            # Failures before the stream starts still arrive as HTTP status codes.
            response.raise_for_status()
            for data in sse_data(response.iter_lines()):
                if data == "[DONE]":
                    return StreamResult("".join(parts), finish_reason, usage)
                chunk = json.loads(data)
                # Error shapes vary by provider. Match the format your provider documents.
                if "error" in chunk:
                    raise StreamError(chunk["error"])
                if chunk.get("usage"):
                    usage = chunk["usage"]
                for choice in chunk.get("choices", []):
                    text = (choice.get("delta") or {}).get("content")
                    if text:
                        parts.append(text)
                        on_delta(text)  # Render each piece as it arrives.
                    if choice.get("finish_reason"):
                        finish_reason = choice["finish_reason"]
    except httpx.TransportError as exc:
        raise StreamInterrupted(f"transport failed: {exc}", "".join(parts)) from exc
    raise StreamInterrupted("stream closed before [DONE]", "".join(parts))
The caller decides what complete means. Treat a result as a finished answer only when finish_reason is "stop" and your own validation passes. A "length" result was cut off by the token limit, and a "content_filter" result is missing content. StreamInterrupted keeps the partial text so the UI can show it with an incomplete label.
Connection management and reconnection
Every streaming client holds an open connection for the length of a generation, so capacity planning counts concurrent connections. A client that reconnects after a drop may land on an instance with no record of its generation.
SSE has a built-in resumption mechanism. Each event can carry an id field, and on reconnect the client sends the last ID it saw in a Last-Event-ID header. Provider streams start with POST, though, so you implement resumption in your own client. The server also needs somewhere to resume from.
A common pattern separates generation from delivery. A worker consumes the provider stream and appends each chunk, with a sequence number, to a shared store keyed by request ID. Any instance can then replay from the client's last acknowledged sequence number and follow the live tail. An in-memory buffer on a single instance cannot do this.
Bound this design before it ships. Cap the queued events or bytes per request, so a slow reader cannot grow memory or storage without limit. Expire replay data after a retention period. Authorize replay, so only the original caller can resume a request ID. Decide whether a client disconnect cancels generation or only detaches delivery. This kind of resumption replays what the worker already stored. Asking the provider to continue from a new prompt is not byte-exact resumption.
Streaming and Caching: Reconciling Two Techniques That Don't Naturally Coexist
Streaming emits a response in pieces, but a cache needs the complete response. The usual resolution treats each path differently:
- Cache miss: stream tokens to the client as they arrive, accumulate them, and write the complete response to the cache after the stream finishes.
- Cache hit: nothing needs generating. Either replay the stored text to the client as valid SSE events, or document a client contract that accepts both JSON and SSE and checks the
Content-Typebefore parsing.
Admit a response to the cache only when all three checks pass: the transport completed, the termination reason shows a complete answer, and application validation succeeded. Otherwise one dropped connection or one truncated generation stores a bad answer that every later hit repeats.
Caching at the gateway changes the trade-off. The WSO2 AI Gateway offers a semantic cache that answers prompts with the same meaning from a vector store. In the policy source at commit 8bfb8f2, that policy declares a buffered response-body mode. It reassembles an SSE response into one JSON document before storing it. This per-policy detail comes from source code, not product documentation, so confirm it for your release. Because the gateway buffers a route whenever one response-body policy needs the full body, which is a documented rule, cache misses on that route arrive as a single response. That trade suits routes with many repeated questions, such as internal help assistants. On open-ended chat routes, leaving the cache off preserves TTFT.
Gateway and Infrastructure Behavior
At an AI gateway, streaming is platform behavior. The platform either passes chunks through or buffers them for a documented reason. The WSO2 AI Gateway is part of the WSO2 API Platform, which governs APIs, AI, and MCP traffic from one control plane. Its documentation on how the AI Gateway handles streaming responses makes a useful worked example.
Pass-through with no configuration
The gateway streams a response whenever the upstream streams it. No configuration is needed on the LLM provider or the LLM proxy. Clients request a stream the same way they would against the provider, with "stream": true in the request body. An LLM proxy inherits the streaming behavior of the provider it consumes.
The all-or-nothing policy rule
Policies that read the response body either process chunks as they arrive or need the complete body. The gateway evaluates this per route, and the rule is all or nothing. If every response-body policy supports streaming, the response streams. If one policy needs the complete body, the gateway buffers the whole response, runs the chain, and sends it in one piece. The result is still correct, but the client sees nothing until the last token.
The chain spans both attachment levels. Organization-wide policies sit on the LLM provider, and per-application policies sit on the LLM proxy. A buffered-only policy at either level buffers the response. The guardrail execution order page says the proxy chain runs before the provider chain on the request path. For buffered responses, it says the response path runs in reverse. Its streaming-mode section says streamed chunks pass through the proxy chain first and then the provider chain. Verify the chunk order for the release you deploy before relying on it. Policies that never read the response body do not affect streaming. That group includes authentication, request-side rate limiting, header policies, and prompt management.
The documentation confirms the route-wide rule but does not list each policy's mode. The policy source shows which side of the rule each policy falls on. At commit 8bfb8f2 of the wso2/gateway-controllers repository, the declared response-body modes break down like this:
| Streams chunk by chunk | Needs the complete body (buffers the route) |
|---|---|
| Sentence Count, Word Count, Content Length, Regex, URL, and PII Masking Regex guardrails | JSON Schema guardrail, Semantic Cache, Azure Content Safety, AWS Bedrock Guardrail |
These modes come from source code at that commit, not from documentation, so confirm them against the policy versions you deploy. One buffered-only guardrail added for a compliance review can quietly remove streaming from a route.
Gating policies
A streaming-capable guardrail can still hold bytes back for a moment. A minimum sentence count cannot be judged on content the policy has not seen. Such a policy accumulates chunks until it has enough content to decide, releases what it holds, and then processes each later chunk as it arrives. The client sees a short pause at the start rather than a wait for the full response.
MCP proxies
Response bodies on MCP proxies stay buffered, even when the MCP server streams its reply. Request bodies stream under the same rules as other routes.
Token usage on streamed responses
Token counts drive analytics, cost tracking, and token-based rate limiting. On a streamed response, the gateway reads them from the usage block in the final events. For OpenAI Chat Completions, request the optional final usage chunk with stream_options.include_usage set to true. Other OpenAI-compatible providers vary, so check their docs. The OpenAI Responses API is a separate contract. It uses typed events and reports usage on its terminal response object, such as the one in response.completed. A Chat Completions request looks like this:
{
  "model": "gpt-4o-mini",
  "stream": true,
  "stream_options": { "include_usage": true },
  "messages": [{ "role": "user", "content": "Summarize this incident report." }]
}
Anthropic reports token counts in its stream by default. When a stream carries no usage block, the gateway still emits one analytics event after the stream closes, but its token metrics are empty. Token-based rate limiting and cost tracking then have nothing to count for that request. Interrupted streams can lose the final usage chunk too. Record such requests as unknown or unreconciled usage, not as zero usage. If budgets depend on token counts, treat stream_options as part of every Chat Completions client's contract.
Timeouts on long streams
A streamed response holds the route open for the whole generation. In the AI Gateway's default configuration, the route timeout is 60 seconds and covers the entire upstream response. The default stream idle timeout is 300 seconds. Long generations can exceed the route default, so raise it per API in the resilience block, as the AI Gateway's timeouts and resilience guide describes.
When a gateway is worth it for streamed traffic
A single service calling one provider can handle streaming in application code. A gateway earns its place when these pressures appear:
- Multiple models or providers. Streaming, authentication, and policy need to behave the same way across every provider you call.
- Spend attribution. Token usage from streams has to be captured and assigned to a team or application. That is the basis of cost tracking for LLM traffic.
- Regulated data in prompts or responses. Guardrails must run on streamed output, and you need to know which of them force buffering.
- Production scale. Many long-lived connections need consistent timeouts, analytics, and rate limits across every service that streams.
Conclusion
Turning on streaming takes one parameter. Keeping it working takes attention at every layer between the model and the reader. The provider has to stream, and every hop on both legs has to pass chunks through. The client has to tell a clean finish from a dropped connection. At the gateway, every response-body policy on the route has to support streaming.
Streaming failures also tend to be silent. A buffering proxy returns a correct answer late. A missing usage block leaves a request uncounted. A truncated stream can look finished. So treat these checks as part of every release, not something you discover in an incident review. Test each hop with curl -N, and send stream_options on Chat Completions requests wherever you count tokens. Review a route's policy chain whenever someone adds a guardrail or a cache.
To see how streaming works alongside guardrails, routing, and token-based rate limiting from one control plane, explore the WSO2 AI Gateway.
Frequently Asked Questions
What is Server-Sent Events (SSE) and why do LLM APIs use it?
SSE is a web standard that lets a server push a series of text events over one HTTP response. LLM APIs use it because tokens are produced in order and only need to flow from server to client.
How do I handle errors that happen in the middle of a stream?
Trust the HTTP status only for the start of the stream. After that, watch for error events inside the stream and for the endpoint's documented completion signal, which differs by provider. Then check the termination reason, because a stream can end cleanly after the token limit truncated the answer. Show partial output as incomplete.
Why does my streaming response stop working behind a reverse proxy?
The proxy is most likely buffering the response body and forwarding it only once it is complete. Turn off response buffering for streaming routes, then check compression and CDN layers.
Can you combine streaming with response caching?
Yes. Stream on a cache miss and store the full response once the stream completes. Return cache hits as complete responses or replay them as SSE events. A cache that runs as a full-body gateway policy buffers misses on its route instead of streaming them.
Do streamed LLM responses report token usage the same way as non-streamed ones?
Not always. OpenAI Chat Completions includes usage in a stream only when the request sets stream_options with include_usage. The OpenAI Responses API reports usage on its terminal response event. Anthropic includes usage in its stream events by default.

